This is the full developer documentation for har.fyi
# har.fyi
> A new reference doc for the HTTP Archive dataset
## Next steps
[Section titled “Next steps”](#next-steps)
Start querying
Learn how to start [querying HTTP Archive on BigQuery](/guides/getting-started/)
Explore table schemas
Learn about the [`pages`](/reference/tables/pages/) table
Contribute to har.fyi
Contribute to the project on [GitHub](https://github.com/HTTPArchive/har.fyi)
Learn more about HTTP Archive
See [httparchive.org](https://httparchive.org/)
Ask us anything
Start a thread on the [HTTP Archive discussion forum](https://discuss.httparchive.org/)
# Getting started
> Using HTTP Archive on BigQuery for the first time
The [HTTP Archive](https://httparchive.org) is an open source project that tracks how the web is built. Historical data is provided to show how the web is constantly evolving, and the project is frequently used for research by the web community, scholars and industry leaders. If you are interested in digging into the HTTP Archive and are not sure where to start, then this guide should help you get started quickly.
There are over 1 million pages tracked on desktop and emulated mobile in the most recent HTTP Archive data, and the historical data goes back to 2010. While the HTTP Archive website makes a lot of information available via [curated reports](https://httparchive.org/reports), analyzing the raw data is a powerful way of answering your questions about the web.
All of the data collected by the HTTP Archive is available via [Google BigQuery](https://cloud.google.com/bigquery/). This makes analyzing the data easy because all of the storage and indexing is taken care of for you. And with the processing power behind BigQuery, even some of the most complex queries runs in seconds.
This document is an update to [Ilya Grigorik’s 2013 introduction](https://www.igvita.com/2013/06/20/http-archive-bigquery-web-performance-answers/), and walks you through everything you need to get started accessing BigQuery and analyzing the data.
## Setting up BigQuery to Access the HTTP Archive
[Section titled “Setting up BigQuery to Access the HTTP Archive”](#setting-up-bigquery-to-access-the-http-archive)
In order to access the HTTP Archive via BigQuery, you’ll need a Google account. To document this process for new visitors, this example uses a new Google account that has never logged into any Google Cloud services.
1. Navigate to the [Google Cloud Projects Page](https://console.cloud.google.com/start) and log in with your Google account if prompted. If this is your first time accessing Google Cloud, you may be prompted to accept the terms of service. Once you are logged in, you’ll see a page like this:
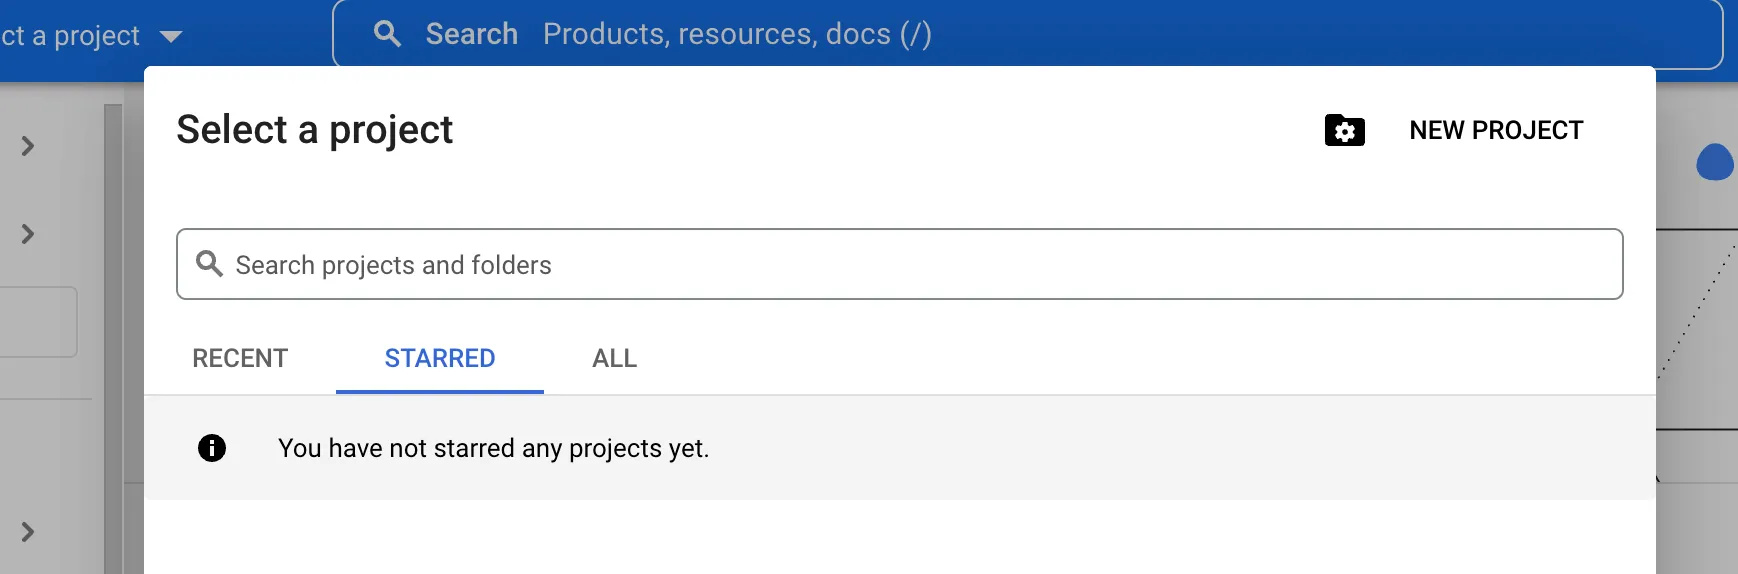
2. Click **Select a project** and then **New Project**. This takes you to a New Project page.
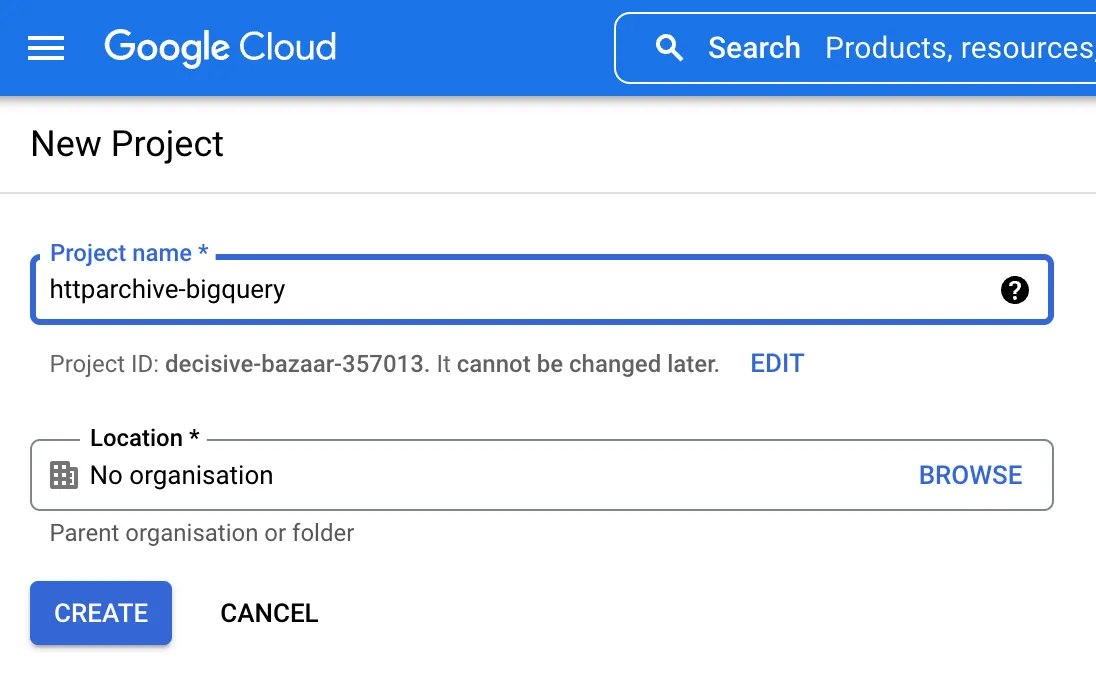
3. Give your project a name and then click the **Create** button.
4. Optional: Enable Billing by clicking on the Billing menu item and adding your billing information.
Note
BigQuery has a [free tier](https://cloud.google.com/bigquery/pricing#free-tier) that you can use to get started without enabling billing. At the time of this writing, the free tier allows 10GB of storage and 1TB of data processing per month. Google also provides a [$300 credit for new accounts](https://cloud.google.com/free/docs/frequently-asked-questions#free-trial).
5. Navigate to the [BigQuery console](https://console.cloud.google.com/bigquery) where you should see your project, with no data.
6. In order to add the HTTP Archive tables to your project, click on the **+ Add** button on top of the Explorer sidebar and choose the **Star a project by name** option from the side menu.
7. Type in `httparchive` (case-sensitive) and click **STAR**.
8. You should now see the HTTP Archive data set pinned:
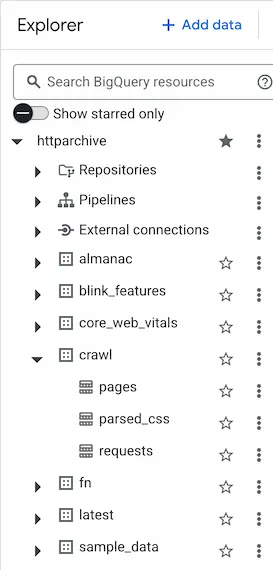
9. Let’s run a quick sample query to confirm access is all working. Navigate to the `crawl` dataset and select the `pages` table:
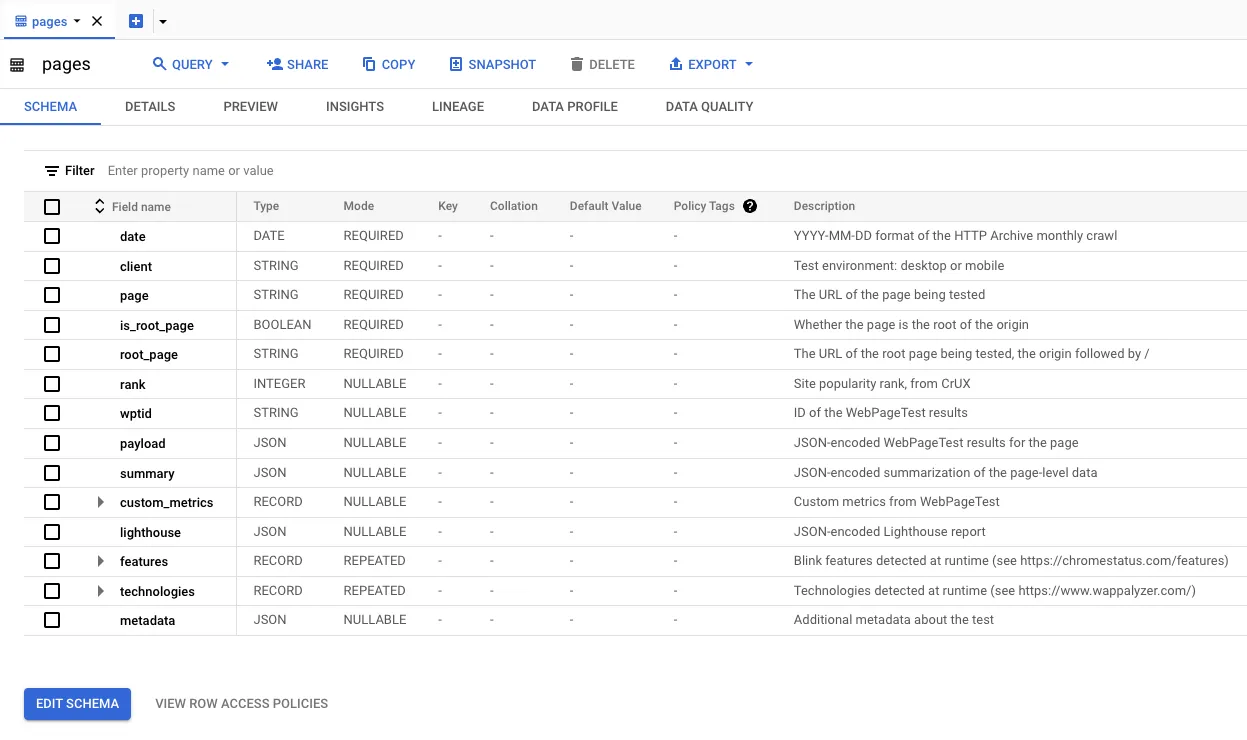
10. Click on the **QUERY** button and select **In a new tab**:
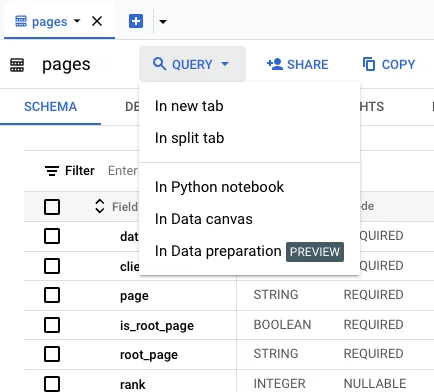
11. Change the query to take a small sample of the table (e.g. `SELECT *`), click the `RUN` button and you should see the results of your query.
Danger
The size of the tables you query are important because BigQuery is billed based on the number of processed data. There is 1TB of processed data included in the free tier, so running a full scan query on one of the larger tables can easily eat up your quota. This is where it becomes important to design queries that process only the data you wish to explore.
HTTP Archive collecting metadata from millions of websites each month, an the dataset is *extremely large*—multiple petabytes.
See the guide on [minimizing query costs](/guides/minimizing-costs/) to learn more.
Also, take a moment setting up [cost controls](https://cloud.google.com/bigquery/docs/custom-quotas) to be informed of the costs inqurred throughout the month.
```sql
SELECT *
FROM `httparchive.crawl.pages` TABLESAMPLE SYSTEM (0.00001 PERCENT)
WHERE date = "2024-05-01"
```
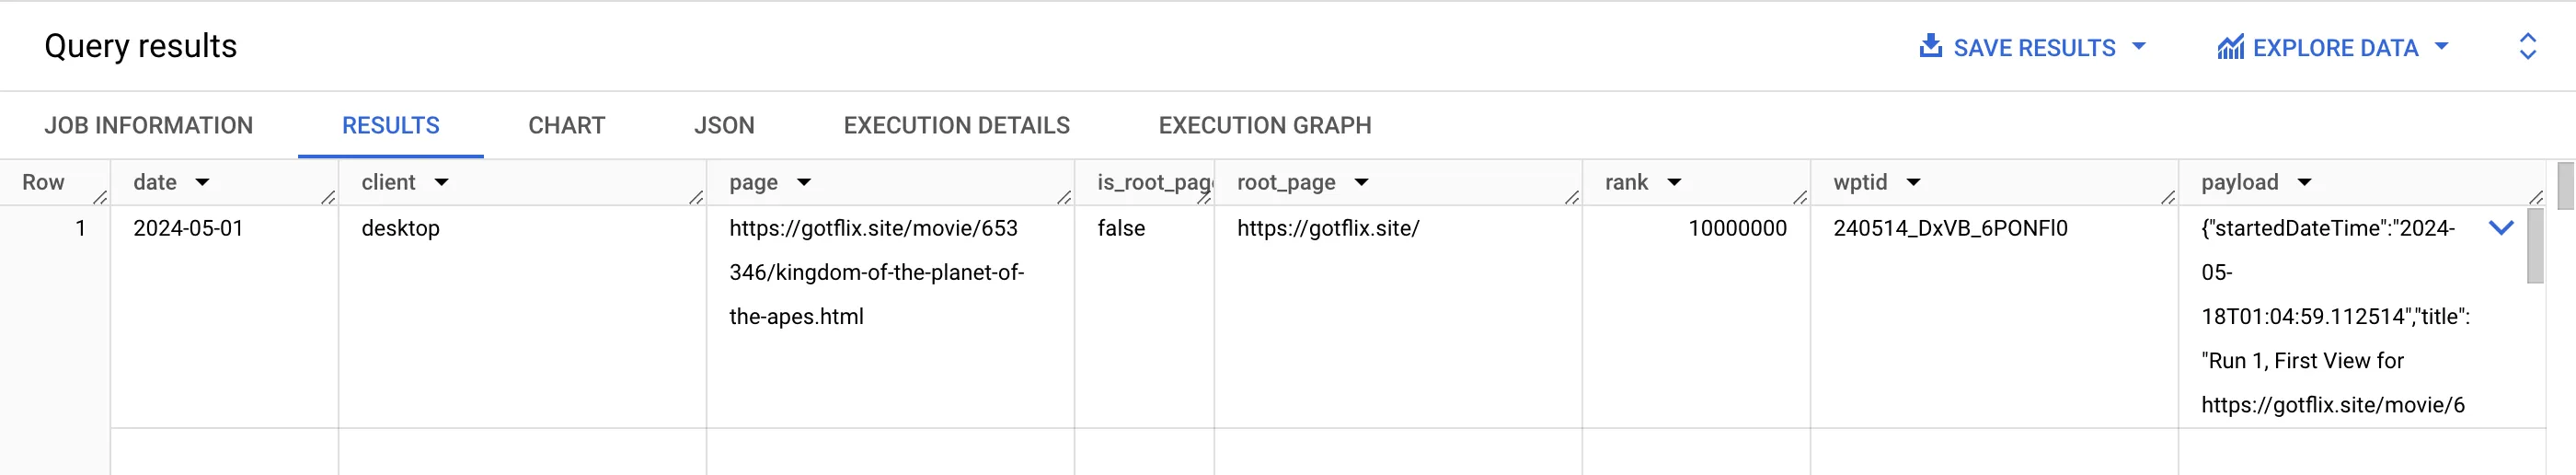
In the next section, we explore the structure of these tables so you can start digging in!
## Understanding how the tables are structured
[Section titled “Understanding how the tables are structured”](#understanding-how-the-tables-are-structured)
So, now you have access! But what do you have access to?
In order to understand what each of these tables contain, you can click on the table name and view the details. For example, if you expand the `crawl` dataset and click on the `pages` table you can see the schema. Clicking **Details** tells you some information about the table, such as its size and the number of rows. Clicking **Preview** shows an example of some data from the table.
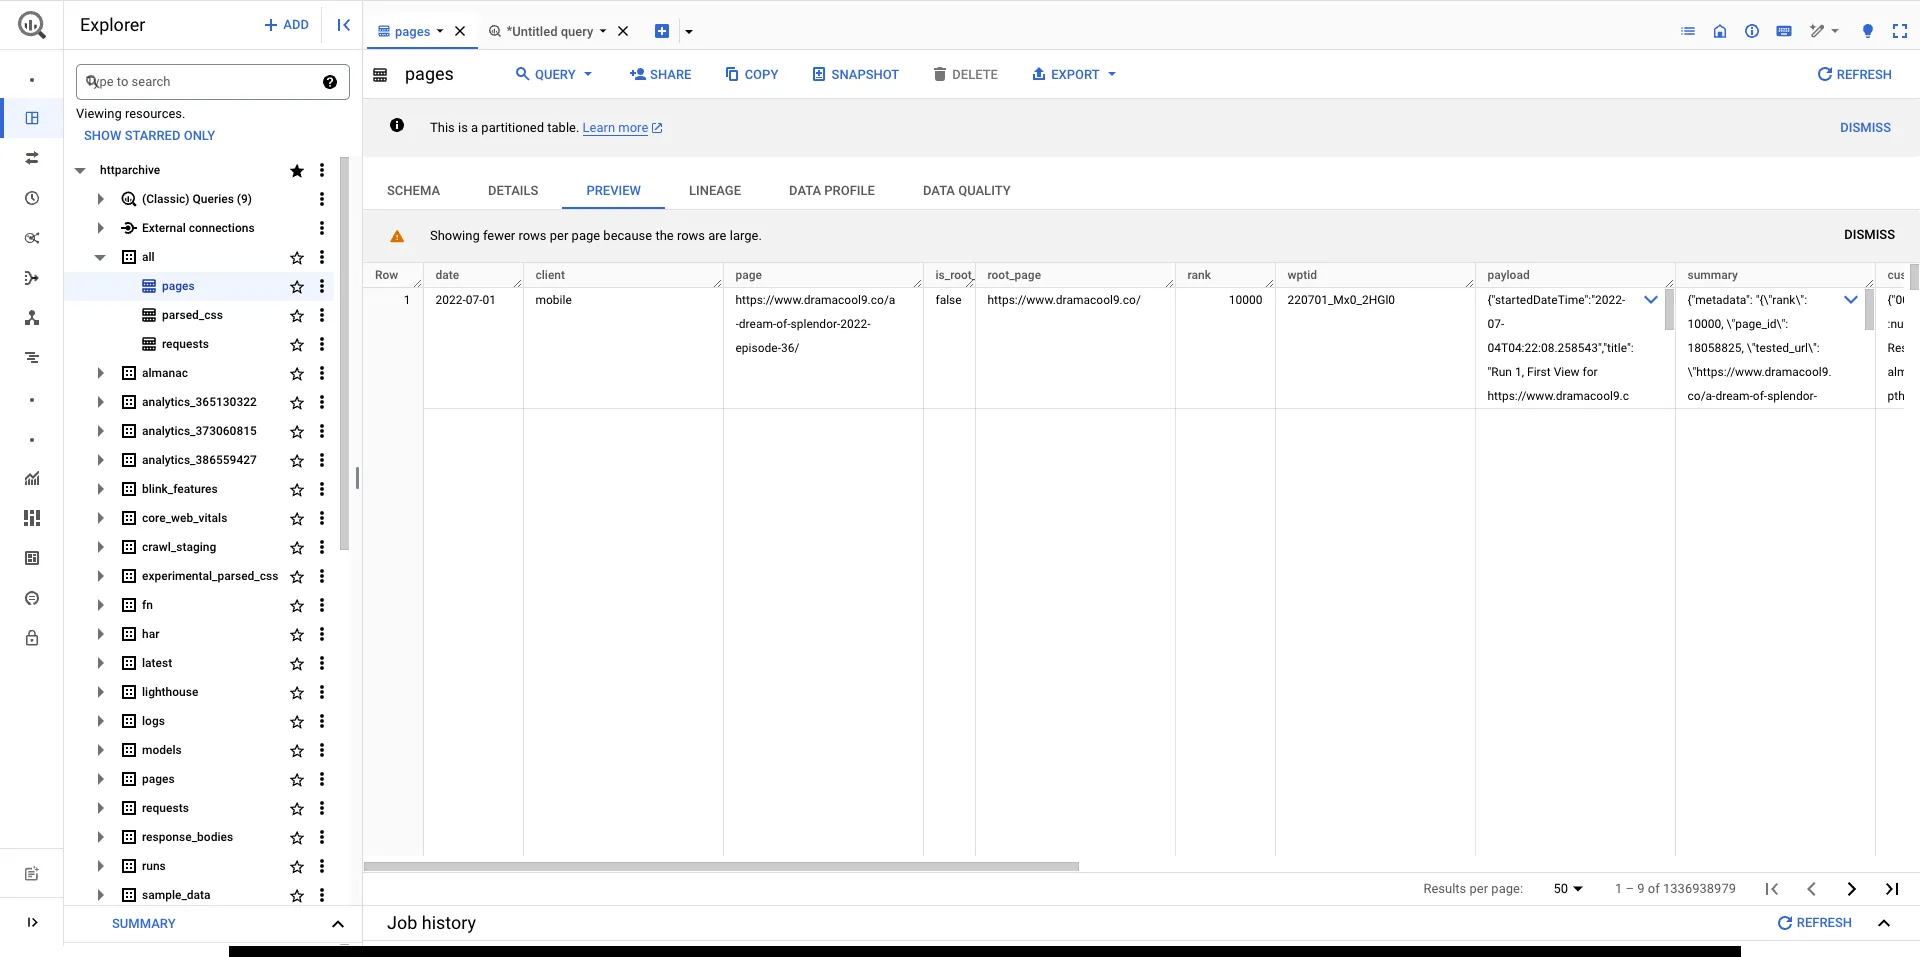
Some of the types of tables you’ll find useful when getting started are described below.
### HAR Tables
[Section titled “HAR Tables”](#har-tables)
The HTTP Archive stores detailed information about each page load in [HAR (HTTP Archive) files](https://en.wikipedia.org/wiki/.har). Each HAR file is JSON formatted and contains detailed performance data about a web page. The [specification for this format](https://w3c.github.io/web-performance/specs/HAR/Overview.html) is produced by the Web Performance Working Group of the W3C. The HTTP Archive splits each HAR file into multiple BigQuery tables, which are described below.
* [`httparchive.crawl.pages`](/reference/tables/pages/) - HAR extract for each page url.
* [`httparchive.crawl.requests`](/reference/tables/requests/) - HAR extract for each resource.
You’ll find JSON encoded HAR files for pages, requests, lighthouse reports and even response bodies! The table below outlines what these tables include.
| Table | Monthly Size (Oct 2024) | History Since |
| -------------- | ----------------------- | ------------- |
| crawl.pages | \~30 TB | June 2011 |
| crawl.requests | \~199 TB | June 2011 |
### Blink Features Tables
[Section titled “Blink Features Tables”](#blink-features-tables)
* [`httparchive.blink_features.usage`](https://console.cloud.google.com/bigquery?ws=!1m5!1m4!4m3!1shttparchive!2sblink_features!3susage):
* Summary information about the [Blink features](https://chromestatus.com/roadmap) detected on each page.
* Table contains the number, percentage and samples of URLs for each feature.
* This data is also available in the HAR of the `pages` table but is extracted into the `blink_features` tables for easy lookup.
* This table is \~1 GB as of Oct 2024.
## Some Example Queries to Get Started Exploring the Data
[Section titled “Some Example Queries to Get Started Exploring the Data”](#some-example-queries-to-get-started-exploring-the-data)
The [HTTP Archive Discuss section](https://discuss.httparchive.org/) has lots of useful examples and discussion on how to analyze this data.
Now that you are all set up, let’s run some queries! Most HTTP Archive users start off examining the summary tables, so we’ll start there as well. Below is a simple aggregate query that tells you how many URLs are contained in the latest HTTP Archive data.
* Query
```sql
SELECT
COUNT(0) AS total_pages
FROM `httparchive.crawl.pages`
WHERE
date = "2024-06-01" AND
client = "desktop" AND
is_root_page
```
* Results
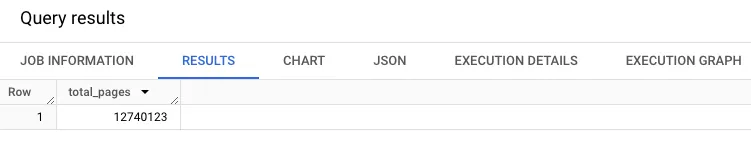
Perhaps you want to JOIN the pages and requests tables together, and see how many page URLs and request URLs are in this data set.
* Query
```sql
SELECT
COUNT(DISTINCT pages.page) AS total_pages,
COUNT(0) AS total_requests
FROM `httparchive.crawl.pages` pages
INNER JOIN `httparchive.crawl.requests`requests
ON pages.page = requests.page
WHERE
pages.date = "2024-06-01" AND
requests.date = "2024-06-01" AND
pages.client = "desktop" AND
requests.client = "desktop" AND
pages.is_root_page AND
requests.is_root_page
```
* Job Information
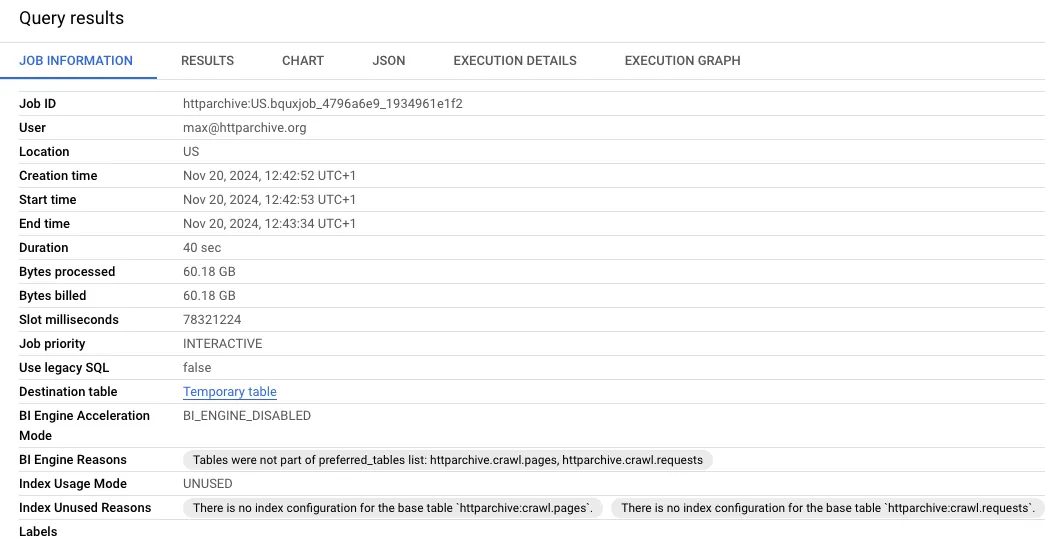
When we look at the results of this, you can see how much data was processed during this query. Writing efficient queries limits the number of bytes processed - which is helpful since that’s how BigQuery is billed.
Note
There is [1TB free per month](https://cloud.google.com/bigquery/pricing#on_demand_pricing).
If you look closely, you’ll notice that this particular query could actually be written without the JOIN. For example, we can count `DISTINCT page` from the `requests` table instead of JOINing the `pages` table. If you run this query, you’ll notice that the results are the same as the previous query, and the processed bytes are a bit less.
```sql
SELECT
COUNT(DISTINCT page) total_pages,
COUNT(0) total_requests
FROM `httparchive.crawl.requests`
WHERE
date = "2024-06-01" AND
client = "desktop" AND
is_root_page
```
Next let’s summarize all of the HTTP requests by a type, and the number of pages that contain at least one request of that type. In the example below, you can see that I added `type` to the SELECT clause, added a GROUP clause and sorted the results by types that have the most requests.
* Query
```sql
SELECT
type,
COUNT(DISTINCT page) total_pages,
COUNT(0) total_requests
FROM `httparchive.crawl.requests`
WHERE
date = "2024-06-01" AND
client = "desktop" AND
is_root_page
GROUP BY type
ORDER BY total_requests DESC
```
* Results
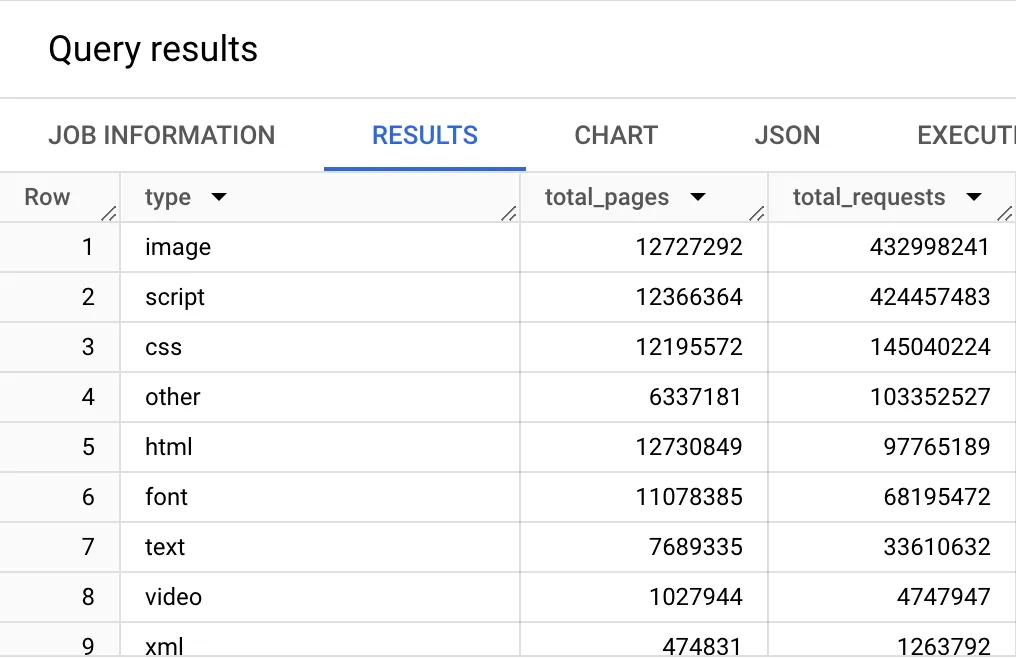
Now things are starting to get interesting. So let’s try to learn something from this basic example. We know from the first example that there are 12.7 million URLs in the latest HTTP Archive dataset. Let’s calculate the percent of pages that have each resource type. To do this, we’ll divide the number of pages by the total pages (using our first query as a subquery). Then we’ll use a `ROUND()` function to trim the result to 2 decimal points.
* Query
```sql
WITH requests AS (
SELECT
type,
page,
COUNT(0) OVER () AS requests_total,
COUNT(DISTINCT page) OVER () AS pages_total,
FROM `httparchive.crawl.requests`
WHERE
date = "2024-06-01" AND
client = "desktop" AND
is_root_page
)
SELECT
type,
COUNT(DISTINCT page) AS pages_total,
ANY_VALUE(requests_total) AS requests_total,
ROUND(COUNT(DISTINCT page) / ANY_VALUE(pages_total), 2) AS pages_percent
FROM requests
GROUP BY type
ORDER BY pages_percent DESC
```
* Results
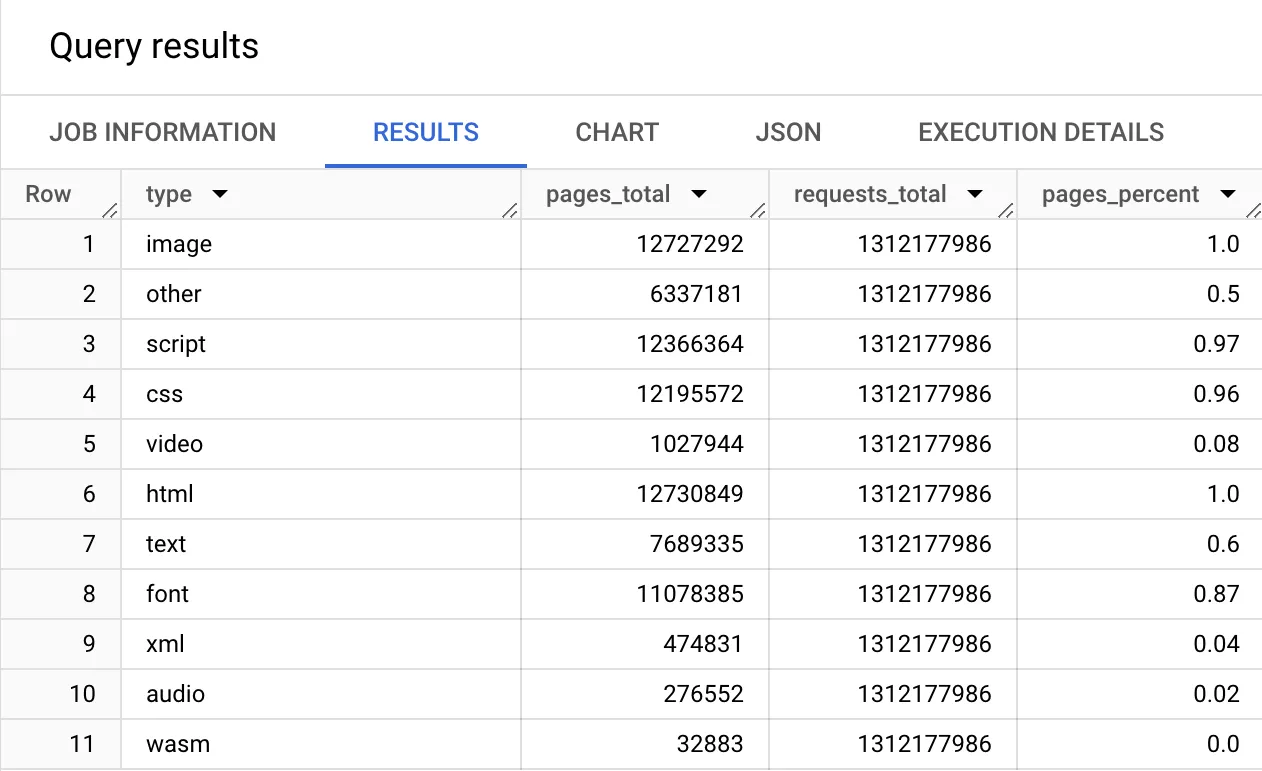
When analyzing the results from this, you can see the % of websites that use different resource types. You can see that:
* 100% of sites have HTML and at least one image,
* 97% have at least 1 script resource,
* 96% load at least 1 CSS style,
* and 87% load fonts on their homepage, etc.
To explore more interactive examples, read the [Guided Tour](/guides/guided-tour/).
If you want to explore deeper you have everything you need - infrastructure, documentation, community. Enjoy exploring this data and feel free to share your results and ask questions on the [HTTP Archive Discuss section](https://discuss.httparchive.org/).
# Guided Tour
> HTTP Archive data analysis in BigQuery
The HTTP Archive contains a tremendous amount of information that can be used to understand the evolution of the web. And since the raw data is available in Google BigQuery, you can start digging into it with a minimal amount of setup!
If you are new to BigQuery, then the [Getting Started guide](/guides/getting-started/) will walk you through the basic setup. That guide ends with a sample query that explores MIME types from the `pages` tables. In this guide, we’ll explore more of the tables and build additional queries that you can learn from. The easiest way to get started is by following along, testing some of the queries and learning from them. If you need any help then there is plenty of support available from the community at .
**Prerequisites:**
* This guide assumes that you’ve completed the setup from the [Getting Started guide](/guides/getting-started/).
* You would be safe processing extremely-large tables contained in this dataset if you follow the [minimizing query costs guide](/guides/minimizing-costs/).
* It also assumes some familiarity with [Google SQL](https://docs.cloud.google.com/bigquery/docs/introduction-sql).
This guide is split into multiple sections, each one focusing on different tables in the HTTP Archive. Each section builds on top of the previous one:
1. [Exploring the `httparchive.crawl.pages` tables](https://colab.research.google.com/github/HTTPArchive/har.fyi/blob/main/workbooks/exploring_httparchive-crawl-pages_tables.ipynb)
2. [Exploring the `httparchive.crawl.requests` tables](https://colab.research.google.com/github/HTTPArchive/har.fyi/blob/main/workbooks/exploring_httparchive-crawl-requests_tables.ipynb)
3. [JOINing `pages` and `requests` tables](https://colab.research.google.com/github/HTTPArchive/har.fyi/blob/main/workbooks/exploring_pages_and_requests_tables_joined.ipynb)
Caution
HTTP Archive uses clustered tables. BigQuery [doesn’t guarantee](https://cloud.google.com/bigquery/docs/clustered-tables#clustered_table_pricing:~:text=BigQuery%20might%20not%20be%20able%20to%20accurately%20estimate%20the%20bytes%20to%20be%20processed) accuracy of estimations for bytes to be processed when querying clustered tables. For your information the actual bytes processed amount is provided in a comment for each query.
Please also read [Minimizing query costs](/guides/minimizing-costs/) for more details on the topic.
# Minimizing query costs
> Practical tips for minimizing the cost of querying the HTTP Archive dataset
The HTTP Archive dataset is large and complex, and it’s easy to write queries that are slow and expensive. All BigQuery users have a free quota of 1 TB per month. To stretch your free quota as far as possible, you’ll want to minimize the amount of data that your queries scan. This guide provides some practical tips for minimizing the cost of querying the HTTP Archive dataset.
## Use cluster columns
[Section titled “Use cluster columns”](#use-cluster-columns)
| Table | Partitioned by | Clustered by |
| ---------------------------- | -------------- | --------------------------------------------- |
| `httparchive.crawl.pages` | `date` | 1.`client` 2.`is_root_page` 3.`rank` 4.`page` |
| `httparchive.crawl.requests` | `date` | 1.`client` 2.`is_root_page` 3.`type` 4.`rank` |
For example, the `httparchive.crawl.pages` table is [partitioned](https://cloud.google.com/bigquery/docs/partitioned-tables) by `date` and [clustered](https://cloud.google.com/bigquery/docs/clustered-tables) by the `client`, `is_root_page`, `rank` and `page` columns, which means that queries that filter on these columns will be much faster and cheaper than queries that don’t.
Caution
[Cluster column ordering](https://docs.cloud.google.com/bigquery/docs/clustered-tables#cluster_column_ordering) is important. BigQuery can take full advantage of clustering if the query filters on the clustered columns in the order they are defined. For example, a query that filters on `client` and `is_root_page` will be able to take full advantage of clustering, but a query that filters on `page` will not be able to take full advantage (but will still be considerably quicker/cheaper than a query that does not use any clustered columns). BigQuery [doesn’t guarantee](https://cloud.google.com/bigquery/docs/clustered-tables#clustered_table_pricing:~:text=BigQuery%20might%20not%20be%20able%20to%20accurately%20estimate%20the%20bytes%20to%20be%20processed) accuracy of estimations for ‘Bytes processed’ when querying clustered tables ([Issue Link](https://issuetracker.google.com/issues/176795805)). The actual data volume may be smaller than the amount provided in the estimate.
Tip
Filter by the top 1k websites. This is the smallest rank bucket and will result in the smallest sample of data being scanned.
```sql
SELECT
page
FROM
`httparchive.crawl.pages`
WHERE
date = '2023-05-01' AND
client = 'desktop' AND
rank <= 1000
```
Tip
Use the `type` column for `requests` table as often you may only be interested in `html` and `script` contents but not `css` for example.
```sql
SELECT
page
FROM
`httparchive.crawl.requests`
WHERE
date = '2023-05-01' AND
client = 'desktop' AND
rank <= 1000 AND
type IN ('html', 'script')
```
This is particularly relevant if using the `response_bodies` or `payload` columns. But these are large columns so try to avoid using them where at all possible. Also note that binary response bodies (e.g. images and fonts) are not stored, so these are mostly `html`, `script`, and `css` so selecting all three of those will not save much.
## Use the `RECORD` columns
[Section titled “Use the RECORD columns”](#use-the-record-columns)
Some of our columns in the table are structured `RECORD` columns. When querying these you only pay for the costs of the records needed.
```sql
SELECT
custom_metrics
FROM
`httparchive.crawl.pages`
WHERE
date = '2023-05-01' AND
client = 'desktop' AND
rank <= 1000
```
This query will process 329 MB when run as it’s looking at all the custom\_metrics.
However, the same query looking at just the `a11y` custom metrics is much cheaper at 10 MB:
```sql
SELECT
custom_metrics.a11y
FROM
`httparchive.crawl.pages`
WHERE
date = '2023-05-01' AND
client = 'desktop' AND
rank <= 1000
```
## Use `TABLESAMPLE`
[Section titled “Use TABLESAMPLE”](#use-tablesample)
The `TABLESAMPLE` clause allows you to sample a table without scanning the entire table. This is useful for getting a rough idea of the data in a table before running a more expensive query.
For example, without `TABLESAMPLE`:
```sql
SELECT
custom_metrics.other.avg_dom_depth
FROM
`httparchive.crawl.pages`
WHERE
date = '2023-05-01' AND
client = 'desktop'
```
This query will process 6.56 TB when run.
However, the same query with `TABLESAMPLE` at 0.01% is much cheaper:
```sql
SELECT
custom_metrics.other.avg_dom_depth
FROM
`httparchive.crawl.pages` TABLESAMPLE SYSTEM (0.01 PERCENT)
WHERE
date = '2023-05-01' AND
client = 'desktop'
```
This query will only process 680.01 MB when run.
The 0.01% of rows that are sampled are chosen randomly, so the results of the query will be different each time it’s run.
Danger
## Don’t rely on LIMIT
[Section titled “Don’t rely on LIMIT”](#dont-rely-on-limit)
Don’t rely on the `LIMIT` clause to reduce the amount of data scanned. `LIMIT` is applied after the query is run, so the entire table will still be scanned.
For example, this query still processes 6.56 TB:
```sql
SELECT
custom_metrics.other.avg_dom_depth
FROM
`httparchive.crawl.pages`
WHERE
date = '2023-05-01' AND
client = 'desktop'
LIMIT
1
```
## Use RANK
[Section titled “Use RANK”](#use-rank)
An alternative to `TABLESAMPLE`, to get a consistent set of data returning for a subset of data, is to use the `rank` column as mentioned previously. For the top 1,000 or even 10,000 sites:
```sql
SELECT
custom_metrics.other.avg_dom_depth
FROM
`httparchive.crawl.pages`
WHERE
date = '2023-05-01' AND
client = 'desktop' AND
rank <= 1000
```
While this constency is an advantage over `TABLESAMPLE`, annoyingly due to the [previously mentioned bug](https://issuetracker.google.com/issues/176795805), using `rank` will not give an accurate estimate, while `TABLESAMPLE` will. So it can be a bit more of a leap of faith using `rank`.
To get around that you can use the `sample_data` dataset.
## Use the `sample_data` dataset
[Section titled “Use the sample\_data dataset”](#use-the-sample_data-dataset)
The `sample_data` dataset contains 10k subsets of the full pages and requests tables. These tables are useful for testing queries before running them on the full dataset, without the risk of incurring a large query cost.
Table names correspond to their full-size counterparts of the form `[table]_10k` for `crawl.pages` and `crawl.requests` tables. For example, to query the summary data for the subset of 10k pages, you would use the `httparchive.sample_data.pages_10k` table.
In reality as `rank` is part of the clustering of the tables you don’t need to use the `sample_data` dataset. However, due to inaccurate estimates mentioned above, the `sample_data` dataset is safer since it only contains 10,000 pages so even with inaccurate estimates it will be smaller than the full `crawl` dataset.
## Whether to use `TABLESAMPLE`, `rank`, or `sample_data`
[Section titled “Whether to use TABLESAMPLE, rank, or sample\_data”](#whether-to-use-tablesample-rank-or-sample_data)
This comes down largely to a matter of personal preference. Each has their advantage and disadvantage.
| Advantage | `TABLESAMPLE` | `rank` | `sample_data` |
| ----------------------------------- | ------------- | ------ | ------------------------ |
| Consistency of results returned | ❌ | ✅ | ✅ (if run in same month) |
| Accurate estimates | ✅ | ❌ | ✅ |
| Ease of commenting out for full run | ✅ | ✅ | ❌ |
| Allows querying of any months | ✅ | ✅ | ❌ (previous month only) |
| Allows variable sample size | ✅ | ✅ | ❌ |
If they ever fix the estimate bug then `rank` will be a clear winner. Until then use whatever works for you!
## Use table previews
[Section titled “Use table previews”](#use-table-previews)
BigQuery allows you to preview entire rows of a table without incurring a query cost. This is useful for getting a rough idea of the data in a table before running a more expensive query.
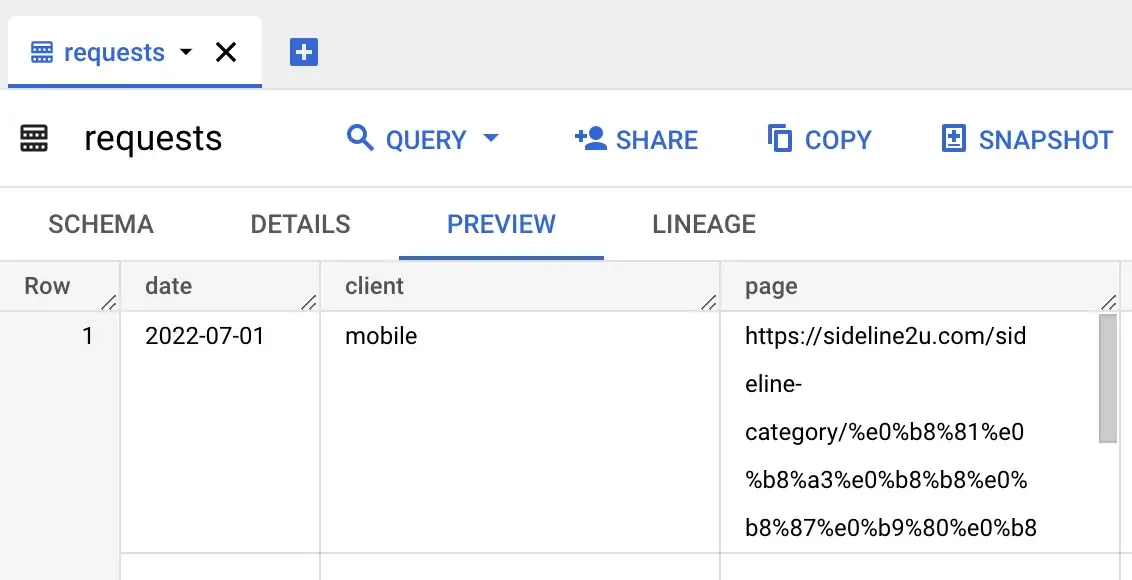
To access the preview, click on a table name from the workspace explorer and select the **Preview** tab.
Note that generating the preview may be slow for these tables as they include large payloads. Also note that the text values are truncated by default, so you will need to expand the field to get the full value.
# The HTTP Archive release cycle
> Learn about the process of testing millions of web pages each month
The HTTP Archive dataset is updated each month with data from millions of web pages. This guide explores the end-to-end release cycle from sourcing URLs to publishing results to BigQuery.
[](https://www.plantuml.com/plantuml/uml/RL5DRnCn4BtxLppr60aaEFQ0Aie9eHAQ5BXExEckXMCRUvme5tuxpdgtkrNNKYpvPTxi-xZBGadAqIb3GWVAZFlqz5l5Ybfj8tcf09qTfrVOraPsrZCeu-PBfRuWDujDBXIpav2eQuC3W8RKGHsSOoqs-8n7ZY59dicVRVUZSBeezH244KwS1cctAB4EiK7m-EWDzeMpeGl2CwHd78ENNgbHzBjFZRCB9Udc3K-Ftx8YBVP4mY_kK8-QJApHZYp9wWLp6bOBscZZ5jjoS3Rtk0-9yOiF-6c5NCQUTU-32zq5QPXLXjziR6Aw54fi-l2tS66OakWQ5_xX0yxCVuP15q94v8G3YUwlEKJgE2kCPuvYqKVrHgT1sRQ-zfm5ShqIv-8au-lk-yFR3LCfZVsQORq4PA7E-WwrH3TAO6zK_IqgcMpYTdJtR7tDYatpRNYzd9R7sKflFGYrym5VJszwp9hdJWm9GG8scruaKjAzFV5xVVtMPZFycrdcBUl5jlQQnPKA1yjtzIf7zny0)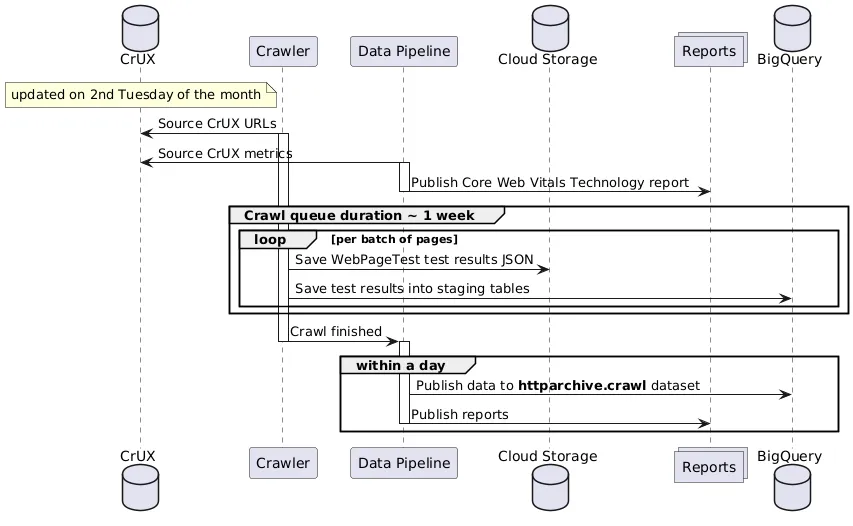
## Sourcing URLs
[Section titled “Sourcing URLs”](#sourcing-urls)
The pages HTTP Archive tests are ultimately sourced from the [Chrome UX Report](https://developer.chrome.com/docs/crux/) (CrUX) dataset. CrUX is a public dataset that contains anonymized, aggregated metrics about real-world Chrome users’ experiences on popular destinations on the web. HTTP Archive takes the *origins* in the public CrUX dataset and classifies them as either desktop and mobile. Origins are segmented by desktop or mobile depending on the [`form_factor`](https://developer.chrome.com/docs/crux/methodology/#form-factor-dimension) dimension in the CrUX schema, which corresponds to the actual device type real visitors used to access the website.
CrUX also includes origins without any distinct form factor data. HTTP Archive classifies these origins as *both* desktop and mobile.
## Running the crawl
[Section titled “Running the crawl”](#running-the-crawl)
Previously, HTTP Archive would start testing each web page (the crawl) on the first of the month. Now, to be in closer alignment with the upstream CrUX dataset, HTTP Archive starts testing pages as soon as the CrUX dataset is available on the second Tuesday of each month. Crawl dates are always rounded down to the first of the month, regardless of which day they actually started. For example, the June 2023 crawl kicks off on the 13th of the month, but the dataset would be accessible on BigQuery under the date `2023-06-01`.
Note
As of [May 2023](https://httparchive.org/reports/state-of-the-web?start=2023_04_01\&end=2023_05_01\&view=list#numUrls) there are 16.6 million mobile pages and 12.8 million desktop pages. It takes 1–2 weeks to test all of these pages, so the crawl is usually complete in the second half of the month.
## Publishing the raw data
[Section titled “Publishing the raw data”](#publishing-the-raw-data)
As each page’s test results are completed, the raw data is saved to a public Google Cloud Storage bucket. Once the crawl is complete, the data is processed and published to BigQuery. The `httparchive.crawl` dataset is available to the public for analysis.
## Generating reports
[Section titled “Generating reports”](#generating-reports)
The reports on the [HTTP Archive website](https://httparchive.org/reports) and auxilliary ones like the [Core Web Vitals Technology Report](https://httparchive.org/reports/techreport/landing) are automatically generated as soon as the data is available in BigQuery.
# Lighthouse blob
> Reference docs for the Lighthouse blob
*Appears in: [`pages`](/reference/tables/pages/) table*\
*As: [`lighthouse`](/reference/tables/pages/#lighthouse)*
JSON-encoded blob of Lighthouse data for the page.
**The actual schema of the Lighthouse object is liable to change depending on the page and Lighthouse version. See the [Lighthouse documentation](https://github.com/GoogleChrome/lighthouse/blob/main/docs/understanding-results.md) for the most up-to-date information.**
# Page metadata blob
> Reference docs for the HAR page metadata blob
*Appears in: [`pages`](/reference/tables/pages/) table*\
*As: [`metadata`](/reference/tables/pages/#metadata)*
JSON-encoded HTTP Archive metadata about the page that was tested.
An example of the decoded object
```json
{
"crawl_depth": 1,
"layout": "Desktop",
"link_depth": 0,
"parent_page_test_id": "241008_Dx133_8DPZ7",
"parent_page_url": "https://httparchive.org/",
"rank": 5000000,
"retry_count": 0,
"root_page_test_id": "241008_Dx133_8DPZ7",
"root_page_url": "https://httparchive.org/",
"tested_url": "https://httparchive.org/faq",
"visited": [
"https://httparchive.org/",
"https://httparchive.org/faq"
]
}
```
Note
There is a lot of other page-level metadata in the [custom metrics](/reference/structs/custom-metrics/), which are custom pieces of JavaScript (see [source code](https://github.com/HTTPArchive/custom-metrics/)) run during the crawl to extract information from the page.
Check the custom metrics before falling back to `response_body`. Custom metrics include the post-JavaScript DOM, are far less brittle than regexing HTML, and are significantly faster and cheaper to query.
For example, to get the `title` and `meta_description` you can use:
```sql
SELECT
page,
custom_metrics.wpt_bodies.title.rendered.primary.text AS title,
custom_metrics.wpt_bodies.meta_description.rendered.primary.text AS meta_description.
FROM
`httparchive.crawl.pages`
WHERE
...
```
The [source code](https://github.com/HTTPArchive/custom-metrics/) of the custom metrics can be useful to understand exactly how they are collected.
## Schema
[Section titled “Schema”](#schema)
### `crawl_depth`
[Section titled “crawl\_depth”](#crawl_depth)
Levels of depth from the root page. HTTP Archive is currently configured to crawl one level into a website, so this value will always be `0` or `1`.
A value of `0` means that the page is the root page. A value of `1` means that the page is an *interior* or *secondary page*.
When a root page is being tested, secondary page candidates are collected using the [`crawl-links`](https://github.com/HTTPArchive/custom-metrics/blob/main/dist/crawl_links.js) custom metric. The criteria for candidate pages are:
* The page is linked from the root page
* The page is on the same origin as the root page
* The page is not the same as the root page
* The link to the page is visible within the viewport
From the list of candidates, the link with the largest hit area is selected to be tested next. If that test fails, the next largest link is used.
### `layout`
[Section titled “layout”](#layout)
Whether the page was tested in a desktop or mobile environment. Values are `"Desktop"` or `"Mobile"`.
### `link_depth`
[Section titled “link\_depth”](#link_depth)
At a given crawl depth, this value represents the index in the list of pages being tested. Currently, HTTP Archive only crawls one page per level, so this value is always `0`.
Hypothetically, HTTP Archive can crawl multiple pages per level. For example, at crawl depth `0`, the page is the root. Given that there’s only one root page, the `link_depth` would be `0`. At crawl depth `1`, there may be many secondary page candidates. Instead of testing only one of them, HTTP Archive could test multiple secondary pages that are all linked from the root page. These pages would have a `link_depth` of `0`, `1`, `2`, etc, where the smaller indexes represent the pages that are more prominently linked from the preceding page.
### `parent_page_test_id`
[Section titled “parent\_page\_test\_id”](#parent_page_test_id)
The test ID of the parent page. This is useful for debugging purposes.
### `parent_page_url`
[Section titled “parent\_page\_url”](#parent_page_url)
URL of the parent page.
### `rank`
[Section titled “rank”](#rank)
The rank magnitude of the origin, which is a measure of relative popularity.
For example, the page `https://www.example.com/` has a rank of `500000`, which means that the `https://www.example.com` website is in the top 500k most popular, according to the [Chrome UX Report](https://developer.chrome.com/docs/crux/methodology/#popularity-metric).
### `retry_count`
[Section titled “retry\_count”](#retry_count)
The number of times the page was retried. This is useful for debugging purposes.
### `root_page_test_id`
[Section titled “root\_page\_test\_id”](#root_page_test_id)
The test ID of the root page.
### `root_page_url`
[Section titled “root\_page\_url”](#root_page_url)
URL of the root page.
### `tested_url`
[Section titled “tested\_url”](#tested_url)
The actual URL of the page that was intended to be tested.
This is useful when there may be ambiguity caused by redirects or known issues where the certificate request appears before the page itself.
### `visited`
[Section titled “visited”](#visited)
An array of URLs that were visited during the test. This includes the root page and any secondary pages that were tested.
# Page payload blob
> Reference docs for the page payload blob
*Appears in: [`pages`](/reference/tables/pages/) table*\
*As: [`payload`](/reference/tables/pages/#payload)*
JSON-encoded WebPageTest result data for a page.
An example of the decoded object
```json
{
"_LargestContentfulPaintNodeType": "P",
"_LargestContentfulPaintType": "text",
"_LastInteractive": 400,
"_PerformancePaintTiming.first-contentful-paint": 314.80000000447035,
"_PerformancePaintTiming.first-paint": 314.80000000447035,
"_SpeedIndex": 400,
"_TTFB": 232,
"_TTIMeasurementEnd": 3452,
"_URL": "https://www.example.com/",
"_aft": 0,
"_audit_issues": [
{
"code": "QuirksModeIssue",
"details": {
"quirksModeIssueDetails": {
"documentNodeId": 2,
"frameId": "E021D0149DE3689992ECE4DF4B0ECA38",
"isLimitedQuirksMode": false,
"loaderId": "67DD39DE1A5C91FCB7B25B32EB8F7231",
"url": "http://127.0.0.1:8888/orange.html"
}
}
}
],
"_basePageSSLTime": 98,
"_base_page_cdn": "Edgecast",
"_base_page_cname": "",
"_base_page_dns_server": "a.iana-servers.net",
"_base_page_ip_ptr": "",
"_browserVersion": "128.0.0.0",
"_browser_name": "Chrome",
"_browser_version": "128.0.0.0",
"_bytesIn": 1296,
"_bytesInDoc": 1296,
"_bytesOut": 4112,
"_bytesOutDoc": 4112,
"_cached": 0,
"_chromeUserTiming": [
{
"name": "navigationStart",
"time": 39
},
...
],
"_chromeUserTiming.CumulativeLayoutShift": 0,
"_chromeUserTiming.LargestContentfulPaint": 354,
"_chromeUserTiming.LargestTextPaint": 354,
"_chromeUserTiming.TotalLayoutShift": 0,
"_chromeUserTiming.commitNavigationEnd": 285,
"_chromeUserTiming.domComplete": 320,
"_chromeUserTiming.domContentLoadedEventEnd": 320,
"_chromeUserTiming.domContentLoadedEventStart": 320,
"_chromeUserTiming.domInteractive": 320,
"_chromeUserTiming.domLoading": 285,
"_chromeUserTiming.fetchStart": 48,
"_chromeUserTiming.firstContentfulPaint": 354,
"_chromeUserTiming.firstMeaningfulPaint": 354,
"_chromeUserTiming.firstMeaningfulPaintCandidate": 354,
"_chromeUserTiming.firstPaint": 354,
"_chromeUserTiming.loadEventEnd": 320,
"_chromeUserTiming.loadEventStart": 320,
"_chromeUserTiming.markAsMainFrame": 284,
"_chromeUserTiming.navigationStart": 74,
"_chromeUserTiming.responseEnd": 277,
"_chromeUserTiming.unloadEventEnd": 284,
"_chromeUserTiming.unloadEventStart": 284,
"_connections": 1,
"_consoleLog": [
{
"level": "error",
"networkRequestId": "344808.2",
"source": "network",
"text": "Failed to load resource: the server responded with a status of 404 ()",
"timestamp": 1726370503561.599,
"url": "https://www.example.com/favicon.ico"
}
],
"_cpu.CommitLoad": 0,
"_cpu.EventDispatch": 0,
"_cpu.FunctionCall": 0,
"_cpu.HTMLDocumentParser::FetchQueuedPreloads": 0,
"_cpu.Idle": 302,
"_cpu.Layerize": 0,
"_cpu.Layout": 18,
"_cpu.MarkDOMContent": 0,
"_cpu.MarkLoad": 0,
"_cpu.Paint": 0,
"_cpu.ParseHTML": 2,
"_cpu.PrePaint": 0,
"_cpu.ResourceFetcher::requestResource": 0,
"_cpu.UpdateLayoutTree": 0,
"_cpu.V8.GC_TIME_TO_SAFEPOINT": 0,
"_cpu.largestContentfulPaint::Candidate": 0,
"_cpuTimes": {
"CommitLoad": 0,
"EventDispatch": 0,
"FunctionCall": 0,
"HTMLDocumentParser::FetchQueuedPreloads": 0,
"Idle": 302,
"Layerize": 0,
"Layout": 18,
"MarkDOMContent": 0,
"MarkLoad": 0,
"Paint": 0,
"ParseHTML": 2,
"PrePaint": 0,
"ResourceFetcher::requestResource": 0,
"UpdateLayoutTree": 0,
"V8.GC_TIME_TO_SAFEPOINT": 0,
"largestContentfulPaint::Candidate": 0
},
"_cpuTimesDoc": {
"CommitLoad": 0,
"EventDispatch": 0,
"FunctionCall": 0,
"HTMLDocumentParser::FetchQueuedPreloads": 0,
"Idle": 299,
"Layerize": 0,
"Layout": 18,
"MarkDOMContent": 0,
"MarkLoad": 0,
"Paint": 0,
"ParseHTML": 2,
"PrePaint": 0,
"ResourceFetcher::requestResource": 0,
"UpdateLayoutTree": 0,
"V8.GC_TIME_TO_SAFEPOINT": 0,
"largestContentfulPaint::Candidate": 0
},
"_date": 1726370503.1648238,
"_docTime": 320,
"_document_URL": "https://www.example.com/",
"_document_hostname": "www.example.com",
"_document_origin": "https://www.example.com",
"_domComplete": 281,
"_domContentLoadedEventEnd": 280,
"_domContentLoadedEventStart": 280,
"_domElements": 12,
"_domInteractive": 280,
"_domLoading": 0,
"_domTime": 0,
"_edge-processed": true,
"_effectiveBps": 14727,
"_eventName": "Step_1",
"_execution_contexts": [
{
"id": 1,
"name": "",
"origin": "https://www.example.com"
},
...
],
"_final_base_page_request": 0,
"_final_base_page_request_id": "44714C6F6C72B045136D19CA9894886A",
"_final_url": "https://www.example.com/",
"_firstContentfulPaint": 354,
"_firstMeaningfulPaint": 354,
"_firstPaint": 314.80000000447035,
"_fullyLoaded": 323,
"_fullyLoadedCPUms": 610,
"_fullyLoadedCPUpct": 9.41358024700691,
"_gzip_savings": 0,
"_gzip_total": 648,
"_image_savings": 0,
"_image_total": 0,
"_interactivePeriods": [[0, 3452]],
"_largestPaints": [
{
"DOMNodeId": 3,
"event": "LargestTextPaint",
"nodeInfo": {
"bounds": [660, 192.875, 600, 57],
"nodeType": "P",
"styles": {
"background-image": "none"
}
},
"size": 33858,
"time": 354
}
],
"_lastVisualChange": 400,
"_lighthouse.Accessibility": 0.88,
"_lighthouse.BestPractices": 0.96,
"_lighthouse.Performance": 1,
"_lighthouse.Performance.cumulative-layout-shift": 0,
"_lighthouse.Performance.first-contentful-paint": 329.542,
"_lighthouse.Performance.largest-contentful-paint": 329.542,
"_lighthouse.Performance.speed-index": 322,
"_lighthouse.Performance.total-blocking-time": 0,
"_lighthouse.SEO": 0.9,
"_loadEventEnd": 281,
"_loadEventStart": 281,
"_loadTime": 320,
"_main_frame": "E021D0149DE3689992ECE4DF4B0ECA38",
"_minify_savings": -1,
"_minify_total": -1,
"_optimization_checked": 1,
"_origin_dns": {
"cname": [],
"https": [],
"mx": ["0 ."],
"ns": [
"a.iana-servers.net.",
"b.iana-servers.net."
],
"soa": [
"ns.icann.org. noc.dns.icann.org. 2024081420 7200 3600 1209600 3600"
],
"svcb": [],
"txt": [
"\"v=spf1 -all\"",
"\"wgyf8z8cgvm2qmxpnbnldrcltvk4xqfn\""
]
},
"_osPlatform": "x86_64 x86_64",
"_osVersion": "Linux 6.8.0-1014-gcp",
"_os_version": "Linux 6.8.0-1014-gcp",
"_render": 400,
"_renderBlockingCSS": 0,
"_renderBlockingJS": 0,
"_requests": 2,
"_requestsDoc": 2,
"_requestsFull": 2,
"_responses_200": 1,
"_responses_404": 1,
"_responses_other": 0,
"_result": 99999,
"_run": 1,
"_score_cache": -1,
"_score_cdn": 100,
"_score_combine": -1,
"_score_compress": -1,
"_score_cookies": -1,
"_score_etags": -1,
"_score_gzip": 100,
"_score_keep-alive": 100,
"_score_minify": -1,
"_score_progressive_jpeg": -1,
"_server_rtt": 0,
"_start_epoch": 1726370501.1809506,
"_step": 1,
"_testID": "240912_Dx1XE_EVGML",
"_testStartOffset": 0,
"_testUrl": "https://www.example.com/",
"_test_run_time_ms": 5850,
"_tester": "agents-west-1-kl42-10.138.2.146",
"_titleTime": 76,
"_v8Stats": {
"background": {},
"main_thread": {}
},
"_viewport": {
"dpr": 1,
"height": 993,
"width": 1920
},
"_visualComplete": 400,
"_visualComplete85": 400,
"_visualComplete90": 400,
"_visualComplete95": 400,
"_visualComplete99": 400,
"id": "page_1_0_1",
"pageTimings": {
"_startRender": 400,
"onContentLoad": -1,
"onLoad": 320
},
"startedDateTime": "2024-09-15T03:21:42.914962",
"testID": "240912_Dx1XE_EVGML",
"title": "Run 1, First View for https://www.example.com/"
}
```
## Schema
[Section titled “Schema”](#schema)
### `_LargestContentfulPaintNodeType`
[Section titled “\_LargestContentfulPaintNodeType”](#_largestcontentfulpaintnodetype)
Type: `string`
The node type of the largest contentful paint
### `_LargestContentfulPaintType`
[Section titled “\_LargestContentfulPaintType”](#_largestcontentfulpainttype)
Type: `string`
The type of the largest contentful paint
### `_LastInteractive`
[Section titled “\_LastInteractive”](#_lastinteractive)
Type: `int`
The time when the page was last interactive in milliseconds
### `_PerformancePaintTiming.first-contentful-paint`
[Section titled “\_PerformancePaintTiming.first-contentful-paint”](#_performancepainttimingfirst-contentful-paint)
Type: `float`
The time when the first contentful paint occurred in milliseconds
### `_PerformancePaintTiming.first-paint`
[Section titled “\_PerformancePaintTiming.first-paint”](#_performancepainttimingfirst-paint)
Type: `float`
The time when the first paint occurred in milliseconds
### `_SpeedIndex`
[Section titled “\_SpeedIndex”](#_speedindex)
Type: `int`
The Speed Index score
### `_TTFB`
[Section titled “\_TTFB”](#_ttfb)
Type: `int`
The time to first byte in milliseconds
### `_TTIMeasurementEnd`
[Section titled “\_TTIMeasurementEnd”](#_ttimeasurementend)
Type: `int`
The time when the TTI measurement ended in milliseconds
### `_URL`
[Section titled “\_URL”](#_url)
Type: `string`
The URL of the page
### `_aft`
[Section titled “\_aft”](#_aft)
Type: `int`
The above-the-fold time in milliseconds
### `_audit_issues`
[Section titled “\_audit\_issues”](#_audit_issues)
Type: `array`
Audit issues
### `_basePageSSLTime`
[Section titled “\_basePageSSLTime”](#_basepagessltime)
Type: `int`
The time spent on SSL for the base page in milliseconds
### `_base_page_cdn`
[Section titled “\_base\_page\_cdn”](#_base_page_cdn)
Type: `string`
The CDN used for the base page
### `_base_page_cname`
[Section titled “\_base\_page\_cname”](#_base_page_cname)
Type: `string`
The CNAME used for the base page
### `_base_page_dns_server`
[Section titled “\_base\_page\_dns\_server”](#_base_page_dns_server)
Type: `string`
The DNS server used for the base page
### `_base_page_ip_ptr`
[Section titled “\_base\_page\_ip\_ptr”](#_base_page_ip_ptr)
Type: `string`
The IP PTR used for the base page
### `_browserVersion`
[Section titled “\_browserVersion”](#_browserversion)
Type: `string`
The browser version
### `_browser_name`
[Section titled “\_browser\_name”](#_browser_name)
Type: `string`
The browser name
### `_browser_version`
[Section titled “\_browser\_version”](#_browser_version)
Type: `string`
The browser version
### `_bytesIn`
[Section titled “\_bytesIn”](#_bytesin)
Type: `int`
The number of bytes received in
### `_bytesInDoc`
[Section titled “\_bytesInDoc”](#_bytesindoc)
Type: `int`
The number of bytes received in the document
### `_bytesOut`
[Section titled “\_bytesOut”](#_bytesout)
Type: `int`
The number of bytes sent out
### `_bytesOutDoc`
[Section titled “\_bytesOutDoc”](#_bytesoutdoc)
Type: `int`
The number of bytes sent out in the document
### `_cached`
[Section titled “\_cached”](#_cached)
Type: `int`
Whether the page was cached
### `_chromeUserTiming`
[Section titled “\_chromeUserTiming”](#_chromeusertiming)
Type: `array`
Chrome user timing
### `_chromeUserTiming.CumulativeLayoutShift`
[Section titled “\_chromeUserTiming.CumulativeLayoutShift”](#_chromeusertimingcumulativelayoutshift)
Type: `int`
The cumulative layout shift
### `_chromeUserTiming.LargestContentfulPaint`
[Section titled “\_chromeUserTiming.LargestContentfulPaint”](#_chromeusertiminglargestcontentfulpaint)
Type: `int`
The largest contentful paint
### `_chromeUserTiming.LargestTextPaint`
[Section titled “\_chromeUserTiming.LargestTextPaint”](#_chromeusertiminglargesttextpaint)
Type: `int`
The largest text paint
### `_chromeUserTiming.TotalLayoutShift`
[Section titled “\_chromeUserTiming.TotalLayoutShift”](#_chromeusertimingtotallayoutshift)
Type: `int`
The total layout shift
### `_chromeUserTiming.commitNavigationEnd`
[Section titled “\_chromeUserTiming.commitNavigationEnd”](#_chromeusertimingcommitnavigationend)
Type: `int`
The commit navigation end
### `_chromeUserTiming.domComplete`
[Section titled “\_chromeUserTiming.domComplete”](#_chromeusertimingdomcomplete)
Type: `int`
The DOM complete
### `_chromeUserTiming.domContentLoadedEventEnd`
[Section titled “\_chromeUserTiming.domContentLoadedEventEnd”](#_chromeusertimingdomcontentloadedeventend)
Type: `int`
The DOM content loaded event end
### `_chromeUserTiming.domContentLoadedEventStart`
[Section titled “\_chromeUserTiming.domContentLoadedEventStart”](#_chromeusertimingdomcontentloadedeventstart)
Type: `int`
The DOM content loaded event start
### `_chromeUserTiming.domInteractive`
[Section titled “\_chromeUserTiming.domInteractive”](#_chromeusertimingdominteractive)
Type: `int`
The DOM interactive
### `_chromeUserTiming.domLoading`
[Section titled “\_chromeUserTiming.domLoading”](#_chromeusertimingdomloading)
Type: `int`
The DOM loading in milliseconds
### `_chromeUserTiming.fetchStart`
[Section titled “\_chromeUserTiming.fetchStart”](#_chromeusertimingfetchstart)
Type: `int`
The fetch start in milliseconds
### `_chromeUserTiming.firstContentfulPaint`
[Section titled “\_chromeUserTiming.firstContentfulPaint”](#_chromeusertimingfirstcontentfulpaint)
Type: `int`
The first contentful paint
### `_chromeUserTiming.firstMeaningfulPaint`
[Section titled “\_chromeUserTiming.firstMeaningfulPaint”](#_chromeusertimingfirstmeaningfulpaint)
Type: `int`
The first meaningful paint
### `_chromeUserTiming.firstMeaningfulPaintCandidate`
[Section titled “\_chromeUserTiming.firstMeaningfulPaintCandidate”](#_chromeusertimingfirstmeaningfulpaintcandidate)
Type: `int`
The first meaningful paint candidate
### `_chromeUserTiming.firstPaint`
[Section titled “\_chromeUserTiming.firstPaint”](#_chromeusertimingfirstpaint)
Type: `int`
The first paint
### `_chromeUserTiming.loadEventEnd`
[Section titled “\_chromeUserTiming.loadEventEnd”](#_chromeusertimingloadeventend)
Type: `int`
The load event end
### `_chromeUserTiming.loadEventStart`
[Section titled “\_chromeUserTiming.loadEventStart”](#_chromeusertimingloadeventstart)
Type: `int`
The load event start
### `_chromeUserTiming.markAsMainFrame`
[Section titled “\_chromeUserTiming.markAsMainFrame”](#_chromeusertimingmarkasmainframe)
Type: `int`
The mark as main frame
### `_chromeUserTiming.navigationStart`
[Section titled “\_chromeUserTiming.navigationStart”](#_chromeusertimingnavigationstart)
Type: `int`
The navigation start
### `_chromeUserTiming.responseEnd`
[Section titled “\_chromeUserTiming.responseEnd”](#_chromeusertimingresponseend)
Type: `int`
The response end
### `_chromeUserTiming.unloadEventEnd`
[Section titled “\_chromeUserTiming.unloadEventEnd”](#_chromeusertimingunloadeventend)
Type: `int`
The unload event end
### `_chromeUserTiming.unloadEventStart`
[Section titled “\_chromeUserTiming.unloadEventStart”](#_chromeusertimingunloadeventstart)
Type: `int`
The unload event start
### `_connections`
[Section titled “\_connections”](#_connections)
Type: `int`
The number of connections
### `_consoleLog`
[Section titled “\_consoleLog”](#_consolelog)
Type: `array`
Console logs
### `_cpu.CommitLoad`
[Section titled “\_cpu.CommitLoad”](#_cpucommitload)
Type: `int`
The CPU time spent on commit load in milliseconds
### `_cpu.EventDispatch`
[Section titled “\_cpu.EventDispatch”](#_cpueventdispatch)
Type: `int`
The CPU time spent on event dispatch in milliseconds
### `_cpu.FunctionCall`
[Section titled “\_cpu.FunctionCall”](#_cpufunctioncall)
Type: `int`
The CPU time spent on function call in milliseconds
### `_cpu.HTMLDocumentParser::FetchQueuedPreloads`
[Section titled “\_cpu.HTMLDocumentParser::FetchQueuedPreloads”](#_cpuhtmldocumentparserfetchqueuedpreloads)
Type: `int`
The CPU time spent on HTML document parser fetch queued preloads in milliseconds
### `_cpu.Idle`
[Section titled “\_cpu.Idle”](#_cpuidle)
Type: `int`
The CPU time spent on idle in milliseconds
### `_cpu.Layerize`
[Section titled “\_cpu.Layerize”](#_cpulayerize)
Type: `int`
The CPU time spent on layerize in milliseconds
### `_cpu.Layout`
[Section titled “\_cpu.Layout”](#_cpulayout)
Type: `int`
The CPU time spent on layout in milliseconds
### `_cpu.MarkDOMContent`
[Section titled “\_cpu.MarkDOMContent”](#_cpumarkdomcontent)
Type: `int`
The CPU time spent on marking DOM content in milliseconds
### `_cpu.MarkLoad`
[Section titled “\_cpu.MarkLoad”](#_cpumarkload)
Type: `int`
The CPU time spent on marking load in milliseconds
### `_cpu.Paint`
[Section titled “\_cpu.Paint”](#_cpupaint)
Type: `int`
The CPU time spent on paint in milliseconds
### `_cpu.ParseHTML`
[Section titled “\_cpu.ParseHTML”](#_cpuparsehtml)
Type: `int`
The CPU time spent on parsing HTML in milliseconds
### `_cpu.PrePaint`
[Section titled “\_cpu.PrePaint”](#_cpuprepaint)
Type: `int`
The CPU time spent on pre-paint in milliseconds
### `_cpu.ResourceFetcher::requestResource`
[Section titled “\_cpu.ResourceFetcher::requestResource”](#_cpuresourcefetcherrequestresource)
Type: `int`
The CPU time spent on resource fetcher request resource in milliseconds
### `_cpu.UpdateLayoutTree`
[Section titled “\_cpu.UpdateLayoutTree”](#_cpuupdatelayouttree)
Type: `int`
The CPU time spent on updating layout tree in milliseconds
### `_cpu.V8.GC_TIME_TO_SAFEPOINT`
[Section titled “\_cpu.V8.GC\_TIME\_TO\_SAFEPOINT”](#_cpuv8gc_time_to_safepoint)
Type: `int`
The CPU time spent on V8 GC time to safepoint in milliseconds
### `_cpu.largestContentfulPaint::Candidate`
[Section titled “\_cpu.largestContentfulPaint::Candidate”](#_cpulargestcontentfulpaintcandidate)
Type: `int`
The CPU time spent on largest contentful paint candidate in milliseconds
### `_cpuTimes`
[Section titled “\_cpuTimes”](#_cputimes)
Type: `object`
CPU times
### `_cpuTimesDoc`
[Section titled “\_cpuTimesDoc”](#_cputimesdoc)
CPU times for the document
### `_date`
[Section titled “\_date”](#_date)
The date in Unix timestamp format
### `_docTime`
[Section titled “\_docTime”](#_doctime)
The document time in milliseconds
### `_document_URL`
[Section titled “\_document\_URL”](#_document_url)
The URL of the document
### `_document_hostname`
[Section titled “\_document\_hostname”](#_document_hostname)
The hostname of the document
### `_document_origin`
[Section titled “\_document\_origin”](#_document_origin)
The origin of the document
### `_domComplete`
[Section titled “\_domComplete”](#_domcomplete)
Type: `int`
The DOM complete in milliseconds
### `_domContentLoadedEventEnd`
[Section titled “\_domContentLoadedEventEnd”](#_domcontentloadedeventend)
Type: `int`
The DOM content loaded event end in milliseconds
### `_domContentLoadedEventStart`
[Section titled “\_domContentLoadedEventStart”](#_domcontentloadedeventstart)
Type: `int`
The DOM content loaded event start in milliseconds
### `_domElements`
[Section titled “\_domElements”](#_domelements)
Type: `int`
The number of DOM elements
### `_domInteractive`
[Section titled “\_domInteractive”](#_dominteractive)
Type: `int`
The DOM interactive in milliseconds
### `_domLoading`
[Section titled “\_domLoading”](#_domloading)
Type: `int`
The DOM loading in milliseconds
### `_domTime`
[Section titled “\_domTime”](#_domtime)
Type: `int`
The DOM time in milliseconds
### `_edge-processed`
[Section titled “\_edge-processed”](#_edge-processed)
Type: `boolean`
Whether the page was processed by Edge
### `_effectiveBps`
[Section titled “\_effectiveBps”](#_effectivebps)
Type: `int`
The effective BPS
### `_eventName`
[Section titled “\_eventName”](#_eventname)
Type: `string`
The event name
### `_execution_contexts`
[Section titled “\_execution\_contexts”](#_execution_contexts)
Type: `array`
Execution contexts
### `_final_base_page_request`
[Section titled “\_final\_base\_page\_request”](#_final_base_page_request)
Type: `int`
The final base page request
### `_final_base_page_request_id`
[Section titled “\_final\_base\_page\_request\_id”](#_final_base_page_request_id)
Type: `string`
The final base page request ID
### `_final_url`
[Section titled “\_final\_url”](#_final_url)
Type: `string`
The final URL
### `_firstContentfulPaint`
[Section titled “\_firstContentfulPaint”](#_firstcontentfulpaint)
Type: `int`
The first contentful paint in milliseconds
### `_firstMeaningfulPaint`
[Section titled “\_firstMeaningfulPaint”](#_firstmeaningfulpaint)
Type: `int`
The first meaningful paint in milliseconds
### `_firstPaint`
[Section titled “\_firstPaint”](#_firstpaint)
Type: `float`
The first paint in milliseconds
### `_fullyLoaded`
[Section titled “\_fullyLoaded”](#_fullyloaded)
Type: `int`
The fully loaded time in milliseconds
### `_fullyLoadedCPUms`
[Section titled “\_fullyLoadedCPUms”](#_fullyloadedcpums)
Type: `int`
The fully loaded CPU time in milliseconds
### `_fullyLoadedCPUpct`
[Section titled “\_fullyLoadedCPUpct”](#_fullyloadedcpupct)
Type: `float`
The fully loaded CPU percentage
### `_gzip_savings`
[Section titled “\_gzip\_savings”](#_gzip_savings)
Type: `int`
The bytes saved by gzip compression
### `_gzip_total`
[Section titled “\_gzip\_total”](#_gzip_total)
Type: `int`
The total bytes in gzip compression
### `_image_savings`
[Section titled “\_image\_savings”](#_image_savings)
Type: `int`
The bytes saved by image compression
### `_image_total`
[Section titled “\_image\_total”](#_image_total)
Type: `int`
The total bytes in image compression
### `_interactivePeriods`
[Section titled “\_interactivePeriods”](#_interactiveperiods)
Type: `array`
Interactive periods in milliseconds
### `_largestPaints`
[Section titled “\_largestPaints”](#_largestpaints)
Type: `array`
Largest paints
### `_lastVisualChange`
[Section titled “\_lastVisualChange”](#_lastvisualchange)
Type: `int`
The time of the last visual change in milliseconds
### `_lighthouse.Accessibility`
[Section titled “\_lighthouse.Accessibility”](#_lighthouseaccessibility)
Type: `float`
The Lighthouse accessibility score
### `_lighthouse.BestPractices`
[Section titled “\_lighthouse.BestPractices”](#_lighthousebestpractices)
Type: `float`
The Lighthouse best practices score
### `_lighthouse.Performance`
[Section titled “\_lighthouse.Performance”](#_lighthouseperformance)
Type: `float`
The Lighthouse performance score
### `_lighthouse.Performance.cumulative-layout-shift`
[Section titled “\_lighthouse.Performance.cumulative-layout-shift”](#_lighthouseperformancecumulative-layout-shift)
Type: `int`
The Lighthouse cumulative layout shift
### `_lighthouse.Performance.first-contentful-paint`
[Section titled “\_lighthouse.Performance.first-contentful-paint”](#_lighthouseperformancefirst-contentful-paint)
Type: `float`
The Lighthouse first contentful paint
### `_lighthouse.Performance.largest-contentful-paint`
[Section titled “\_lighthouse.Performance.largest-contentful-paint”](#_lighthouseperformancelargest-contentful-paint)
Type: `float`
The Lighthouse largest contentful paint
### `_lighthouse.Performance.speed-index`
[Section titled “\_lighthouse.Performance.speed-index”](#_lighthouseperformancespeed-index)
Type: `int`
The Lighthouse speed index
### `_lighthouse.Performance.total-blocking-time`
[Section titled “\_lighthouse.Performance.total-blocking-time”](#_lighthouseperformancetotal-blocking-time)
Type: `int`
The Lighthouse total blocking time
### `_lighthouse.SEO`
[Section titled “\_lighthouse.SEO”](#_lighthouseseo)
Type: `float`
The Lighthouse SEO score
### `_loadEventEnd`
[Section titled “\_loadEventEnd”](#_loadeventend)
Type: `int`
The load event end in milliseconds
### `_loadEventStart`
[Section titled “\_loadEventStart”](#_loadeventstart)
Type: `int`
The load event start in milliseconds
### `_loadTime`
[Section titled “\_loadTime”](#_loadtime)
Type: `int`
The load time in milliseconds
### `_main_frame`
[Section titled “\_main\_frame”](#_main_frame)
Type: `string`
The main frame
### `_minify_savings`
[Section titled “\_minify\_savings”](#_minify_savings)
Type: `int`
The bytes saved by minification
### `_minify_total`
[Section titled “\_minify\_total”](#_minify_total)
Type: `int`
The total bytes in minification
### `_optimization_checked`
[Section titled “\_optimization\_checked”](#_optimization_checked)
Type: `int`
Whether optimization checks were performed
### `_origin_dns`
[Section titled “\_origin\_dns”](#_origin_dns)
Type: `object`
Origin DNS
### `_osPlatform`
[Section titled “\_osPlatform”](#_osplatform)
Type: `string`
The OS platform
### `_osVersion`
[Section titled “\_osVersion”](#_osversion)
Type: `string`
The OS version
### `_os_version`
[Section titled “\_os\_version”](#_os_version)
Type: `string`
The OS version
### `_render`
[Section titled “\_render”](#_render)
Type: `int`
The render time in milliseconds
### `_renderBlockingCSS`
[Section titled “\_renderBlockingCSS”](#_renderblockingcss)
Type: `int`
The render blocking CSS time in milliseconds
### `_renderBlockingJS`
[Section titled “\_renderBlockingJS”](#_renderblockingjs)
Type: `int`
The render blocking JS time in milliseconds
### `_requests`
[Section titled “\_requests”](#_requests)
Type: `int`
The number of requests
### `_requestsDoc`
[Section titled “\_requestsDoc”](#_requestsdoc)
Type: `int`
The number of requests in the document
### `_requestsFull`
[Section titled “\_requestsFull”](#_requestsfull)
Type: `int`
The number of full requests
### `_responses_200`
[Section titled “\_responses\_200”](#_responses_200)
Type: `int`
The number of 200 responses
### `_responses_404`
[Section titled “\_responses\_404”](#_responses_404)
Type: `int`
The number of 404 responses
### `_responses_other`
[Section titled “\_responses\_other”](#_responses_other)
Type: `int`
The number of other responses
### `_result`
[Section titled “\_result”](#_result)
Type: `int`
The result code of the test run
### `_run`
[Section titled “\_run”](#_run)
Type: `int`
The run number
### `_score_cache`
[Section titled “\_score\_cache”](#_score_cache)
Type: `int`
The cache score
### `_score_cdn`
[Section titled “\_score\_cdn”](#_score_cdn)
Type: `int`
The CDN score
### `_score_combine`
[Section titled “\_score\_combine”](#_score_combine)
Type: `int`
The combine score
### `_score_compress`
[Section titled “\_score\_compress”](#_score_compress)
Type: `int`
The compress score
### `_score_cookies`
[Section titled “\_score\_cookies”](#_score_cookies)
Type: `int`
The cookies score
### `_score_etags`
[Section titled “\_score\_etags”](#_score_etags)
Type: `int`
The etags score
### `_score_gzip`
[Section titled “\_score\_gzip”](#_score_gzip)
Type: `int`
The gzip score
### `_score_keep-alive`
[Section titled “\_score\_keep-alive”](#_score_keep-alive)
Type: `int`
The keep-alive score
### `_score_minify`
[Section titled “\_score\_minify”](#_score_minify)
Type: `int`
The minify score
### `_score_progressive_jpeg`
[Section titled “\_score\_progressive\_jpeg”](#_score_progressive_jpeg)
Type: `int`
The progressive JPEG score
### `_server_rtt`
[Section titled “\_server\_rtt”](#_server_rtt)
Type: `int`
The server RTT
### `_start_epoch`
[Section titled “\_start\_epoch”](#_start_epoch)
Type: `float`
The start epoch in Unix timestamp format
### `_step`
[Section titled “\_step”](#_step)
Type: `int`
The step number
### `_testID`
[Section titled “\_testID”](#_testid)
Type: `string`
The test ID
### `_testStartOffset`
[Section titled “\_testStartOffset”](#_teststartoffset)
Type: `int`
The test start offset
### `_testUrl`
[Section titled “\_testUrl”](#_testurl)
Type: `string`
The test URL
### `_test_run_time_ms`
[Section titled “\_test\_run\_time\_ms”](#_test_run_time_ms)
Type: `int`
The test run time in milliseconds
### `_tester`
[Section titled “\_tester”](#_tester)
Type: `string`
The tester
### `_titleTime`
[Section titled “\_titleTime”](#_titletime)
Type: `int`
The title time in milliseconds
### `_v8Stats`
[Section titled “\_v8Stats”](#_v8stats)
Type: `object`
V8 stats
### `_viewport`
[Section titled “\_viewport”](#_viewport)
Type: `object`
The viewport dimensions
### `_visualComplete`
[Section titled “\_visualComplete”](#_visualcomplete)
Type: `int`
The visual complete time in milliseconds
### `_visualComplete85`
[Section titled “\_visualComplete85”](#_visualcomplete85)
Type: `int`
The 85th percentile visual complete time in milliseconds
### `_visualComplete90`
[Section titled “\_visualComplete90”](#_visualcomplete90)
Type: `int`
The 90th percentile visual complete time in milliseconds
### `_visualComplete95`
[Section titled “\_visualComplete95”](#_visualcomplete95)
Type: `int`
The 95th percentile visual complete time in milliseconds
### `_visualComplete99`
[Section titled “\_visualComplete99”](#_visualcomplete99)
Type: `int`
The 99th percentile visual complete time in milliseconds
### `id`
[Section titled “id”](#id)
Type: `string`
The page ID
### `pageTimings`
[Section titled “pageTimings”](#pagetimings)
Type: `object`
Page timings
### `startedDateTime`
[Section titled “startedDateTime”](#starteddatetime)
Type: `string`
The start date and time of the page in Unix timestamp format
### `testID`
[Section titled “testID”](#testid)
Type: `string`
The test ID
### `title`
[Section titled “title”](#title)
Type: `string`
The page title
# Page summary blob
> Reference docs for the page summary blob
*Appears in: [`pages`](/reference/tables/pages/) table*\
*As: [`summary`](/reference/tables/pages/#summary)*
JSON-encoded summarization of the page-level data.
An example of the decoded object
```json
{
"SpeedIndex": 400,
"TTFB": 232,
"_connections": 1,
"bytesAudio": 0,
"bytesCss": 0,
"bytesFlash": 0,
"bytesFont": 0,
"bytesGif": 0,
"bytesHtml": 648,
"bytesHtmlDoc": 648,
"bytesImg": 648,
"bytesJS": 0,
"bytesJpg": 0,
"bytesJson": 0,
"bytesOther": 0,
"bytesPng": 0,
"bytesSvg": 0,
"bytesText": 0,
"bytesTotal": 1296,
"bytesVideo": 0,
"bytesWebp": 0,
"bytesXml": 0,
"cdn": "Edgecast",
"crux": {
"collectionPeriod": {
"firstDate": {
"day": 17,
"month": 8,
"year": 2024
},
"lastDate": {
"day": 13,
"month": 9,
"year": 2024
}
},
"key": {
"formFactor": "DESKTOP",
"url": "https://www.example.com/"
},
"metrics": {
...
}
},
"fullyLoaded": 323,
"gzipSavings": 0,
"gzipTotal": 648,
"maxDomainReqs": 1,
"maxage0": 0,
"maxage1": 0,
"maxage30": 2,
"maxage365": 0,
"maxageMore": 0,
"maxageNull": 0,
"numCompressed": 2,
"numDomElements": 12,
"numDomains": 1,
"numErrors": 1,
"numGlibs": 0,
"numHttps": 2,
"numRedirects": 0,
"onContentLoaded": 280,
"onLoad": 320,
"renderStart": 400,
"reqAudio": 0,
"reqCss": 0,
"reqFlash": 0,
"reqFont": 0,
"reqGif": 0,
"reqHtml": 1,
"reqImg": 1,
"reqJS": 0,
"reqJpg": 0,
"reqJson": 0,
"reqOther": 0,
"reqPng": 0,
"reqSvg": 0,
"reqText": 0,
"reqTotal": 2,
"reqVideo": 0,
"reqWebp": 0,
"reqXml": 0,
"visualComplete": 400
}
```
## Schema
[Section titled “Schema”](#schema)
### `SpeedIndex`
[Section titled “SpeedIndex”](#speedindex)
The Speed Index score.
### `TTFB`
[Section titled “TTFB”](#ttfb)
The time to first byte
### `_connections`
[Section titled “\_connections”](#_connections)
The number of connections.
### `bytesAudio`
[Section titled “bytesAudio”](#bytesaudio)
The number of bytes for audio.
### `bytesCss`
[Section titled “bytesCss”](#bytescss)
The number of bytes for CSS.
### `bytesFlash`
[Section titled “bytesFlash”](#bytesflash)
The number of bytes for Flash.
### `bytesFont`
[Section titled “bytesFont”](#bytesfont)
The number of bytes for font.
### `bytesGif`
[Section titled “bytesGif”](#bytesgif)
The number of bytes for GIF.
### `bytesHtml`
[Section titled “bytesHtml”](#byteshtml)
The number of bytes for HTML.
### `bytesHtmlDoc`
[Section titled “bytesHtmlDoc”](#byteshtmldoc)
The number of bytes for HTML document.
### `bytesImg`
[Section titled “bytesImg”](#bytesimg)
The number of bytes for image.
### `bytesJS`
[Section titled “bytesJS”](#bytesjs)
The number of bytes for JavaScript.
### `bytesJpg`
[Section titled “bytesJpg”](#bytesjpg)
The number of bytes for JPG.
### `bytesJson`
[Section titled “bytesJson”](#bytesjson)
The number of bytes for JSON.
### `bytesOther`
[Section titled “bytesOther”](#bytesother)
The number of bytes for other.
### `bytesPng`
[Section titled “bytesPng”](#bytespng)
The number of bytes for PNG.
### `bytesSvg`
[Section titled “bytesSvg”](#bytessvg)
The number of bytes for SVG.
### `bytesText`
[Section titled “bytesText”](#bytestext)
The number of bytes for text.
### `bytesTotal`
[Section titled “bytesTotal”](#bytestotal)
The total number of bytes.
### `bytesVideo`
[Section titled “bytesVideo”](#bytesvideo)
The number of bytes for video.
### `bytesWebp`
[Section titled “bytesWebp”](#byteswebp)
The number of bytes for WebP.
### `bytesXml`
[Section titled “bytesXml”](#bytesxml)
The number of bytes for XML.
### `cdn`
[Section titled “cdn”](#cdn)
The Content Delivery Network provider.
### `crux`
[Section titled “crux”](#crux)
The CrUX data.
### `fullyLoaded`
[Section titled “fullyLoaded”](#fullyloaded)
The fully loaded time.
### `gzipSavings`
[Section titled “gzipSavings”](#gzipsavings)
The bytes saved due to gzip compression.
### `gzipTotal`
[Section titled “gzipTotal”](#gziptotal)
The total bytes in gzip compression.
### `maxDomainReqs`
[Section titled “maxDomainReqs”](#maxdomainreqs)
The maximum number of requests to a domain.
### `maxage0`
[Section titled “maxage0”](#maxage0)
The number of requests with a max-age of 0.
### `maxage1`
[Section titled “maxage1”](#maxage1)
The number of requests with a max-age > 0 and <= 1 day.
### `maxage30`
[Section titled “maxage30”](#maxage30)
The number of requests with a max-age > 1 day and <= 30 days.
### `maxage365`
[Section titled “maxage365”](#maxage365)
The number of requests with a max-age > 30 days and <= 365 days.
### `maxageMore`
[Section titled “maxageMore”](#maxagemore)
The number of requests with a max-age greater than 365 days.
### `maxageNull`
[Section titled “maxageNull”](#maxagenull)
The number of requests with a max-age of null.
### `numCompressed`
[Section titled “numCompressed”](#numcompressed)
The number of compressed files.
### `numDomElements`
[Section titled “numDomElements”](#numdomelements)
The number of DOM elements.
### `numDomains`
[Section titled “numDomains”](#numdomains)
The number of domains.
### `numErrors`
[Section titled “numErrors”](#numerrors)
The number of errors.
### `numGlibs`
[Section titled “numGlibs”](#numglibs)
The number of glibs.
### `numHttps`
[Section titled “numHttps”](#numhttps)
The number of HTTPS requests.
### `numRedirects`
[Section titled “numRedirects”](#numredirects)
The number of redirects.
### `onContentLoaded`
[Section titled “onContentLoaded”](#oncontentloaded)
The onContentLoaded time.
### `onLoad`
[Section titled “onLoad”](#onload)
The onLoad time.
### `renderStart`
[Section titled “renderStart”](#renderstart)
The renderStart time.
### `reqAudio`
[Section titled “reqAudio”](#reqaudio)
The number of requests for audio.
### `reqCss`
[Section titled “reqCss”](#reqcss)
The number of requests for CSS.
### `reqFlash`
[Section titled “reqFlash”](#reqflash)
The number of requests for Flash.
### `reqFont`
[Section titled “reqFont”](#reqfont)
The number of requests for fonts.
### `reqGif`
[Section titled “reqGif”](#reqgif)
The number of requests for GIF.
### `reqHtml`
[Section titled “reqHtml”](#reqhtml)
The number of requests for HTML.
### `reqImg`
[Section titled “reqImg”](#reqimg)
The number of requests for images.
### `reqJS`
[Section titled “reqJS”](#reqjs)
The number of requests for JavaScript.
### `reqJpg`
[Section titled “reqJpg”](#reqjpg)
The number of requests for JPG.
### `reqJson`
[Section titled “reqJson”](#reqjson)
The number of requests for JSON.
### `reqOther`
[Section titled “reqOther”](#reqother)
The number of requests for other.
### `reqPng`
[Section titled “reqPng”](#reqpng)
The number of requests for PNG.
### `reqSvg`
[Section titled “reqSvg”](#reqsvg)
The number of requests for SVG.
### `reqText`
[Section titled “reqText”](#reqtext)
The number of requests for text.
### `reqTotal`
[Section titled “reqTotal”](#reqtotal)
The total number of requests.
### `reqVideo`
[Section titled “reqVideo”](#reqvideo)
The number of requests for video.
### `reqWebp`
[Section titled “reqWebp”](#reqwebp)
The number of requests for WebP.
### `reqXml`
[Section titled “reqXml”](#reqxml)
The number of requests for XML.
### `visualComplete`
[Section titled “visualComplete”](#visualcomplete)
The visualComplete time.
# Request payload blob
> Reference docs for the request payload blob
*Appears in: [`requests`](/reference/tables/requests/) table*\
*As: [`payload`](/reference/tables/requests/#payload)*
JSON-encoded WebPageTest result data for a request.
**The actual schema is liable to change, depending on a request.**
An example of the decoded object
```json
{
"_all_end": 234,
"_all_ms": 233,
"_all_start": 1,
"_body_file": "001-44714C6F6C72B045136D19CA9894886A-body.txt",
"_body_hash": "ea8fac7c65fb589b0d53560f5251f74f9e9b243478dcb6b3ea79b5e36449c8d9",
"_bytesIn": 648,
"_bytesOut": 2143,
"_cacheControl": "max-age=604800",
"_cache_time": null,
"_cached": 0,
"_cdn_provider": "Edgecast",
"_certificates": [
"-----BEGIN CERTIFICATE-----\nMIIHbjCCBlagAwIBAgIQB1vO8waJyK3fE+Ua9K/hhzANBgkqhkiG9w0BAQsFADBZ\nMQswCQYDVQQGEwJVUzEVMBMGA1UEChMMRGlnaUNlcnQgSW5jMTMwMQYDVQQDEypE\naWdpQ2VydCBHbG9iYWwgRzIgVExTIFJTQSBTSEEyNTYgMjAyMCBDQTEwHhcNMjQw\nMTMwMDAwMDAwWhcNMjUwMzAxMjM1OTU5WjCBljELMAkGA1UEBhMCVVMxEzARBgNV\nBAgTCkNhbGlmb3JuaWExFDASBgNVBAcTC0xvcyBBbmdlbGVzMUIwQAYDVQQKDDlJ\nbnRlcm5ldMKgQ29ycG9yYXRpb27CoGZvcsKgQXNzaWduZWTCoE5hbWVzwqBhbmTC\noE51bWJlcnMxGDAWBgNVBAMTD3d3dy5leGFtcGxlLm9yZzCCASIwDQYJKoZIhvcN\nAQEBBQADggEPADCCAQoCggEBAIaFD7sO+cpf2fXgCjIsM9mqDgcpqC8IrXi9wga/\n9y0rpqcnPVOmTMNLsid3INbBVEm4CNr5cKlh9rJJnWlX2vttJDRyLkfwBD+dsVvi\nvGYxWTLmqX6/1LDUZPVrynv/cltemtg/1Aay88jcj2ZaRoRmqBgVeacIzgU8+zmJ\n7236TnFSe7fkoKSclsBhPaQKcE3Djs1uszJs8sdECQTdoFX9I6UgeLKFXtg7rRf/\nhcW5dI0zubhXbrW8aWXbCzySVZn0c7RkJMpnTCiZzNxnPXnHFpwr5quqqjVyN/aB\nKkjoP04Zmr+eRqoyk/+lslq0sS8eaYSSHbC5ja/yMWyVhvMCAwEAAaOCA/IwggPu\nMB8GA1UdIwQYMBaAFHSFgMBmx9833s+9KTeqAx2+7c0XMB0GA1UdDgQWBBRM/tAS\nTS4hz2v68vK4TEkCHTGRijCBgQYDVR0RBHoweIIPd3d3LmV4YW1wbGUub3Jnggtl\neGFtcGxlLm5ldIILZXhhbXBsZS5lZHWCC2V4YW1wbGUuY29tggtleGFtcGxlLm9y\nZ4IPd3d3LmV4YW1wbGUuY29tgg93d3cuZXhhbXBsZS5lZHWCD3d3dy5leGFtcGxl\nLm5ldDA+BgNVHSAENzA1MDMGBmeBDAECAjApMCcGCCsGAQUFBwIBFhtodHRwOi8v\nd3d3LmRpZ2ljZXJ0LmNvbS9DUFMwDgYDVR0PAQH/BAQDAgWgMB0GA1UdJQQWMBQG\nCCsGAQUFBwMBBggrBgEFBQcDAjCBnwYDVR0fBIGXMIGUMEigRqBEhkJodHRwOi8v\nY3JsMy5kaWdpY2VydC5jb20vRGlnaUNlcnRHbG9iYWxHMlRMU1JTQVNIQTI1NjIw\nMjBDQTEtMS5jcmwwSKBGoESGQmh0dHA6Ly9jcmw0LmRpZ2ljZXJ0LmNvbS9EaWdp\nQ2VydEdsb2JhbEcyVExTUlNBU0hBMjU2MjAyMENBMS0xLmNybDCBhwYIKwYBBQUH\nAQEEezB5MCQGCCsGAQUFBzABhhhodHRwOi8vb2NzcC5kaWdpY2VydC5jb20wUQYI\nKwYBBQUHMAKGRWh0dHA6Ly9jYWNlcnRzLmRpZ2ljZXJ0LmNvbS9EaWdpQ2VydEds\nb2JhbEcyVExTUlNBU0hBMjU2MjAyMENBMS0xLmNydDAMBgNVHRMBAf8EAjAAMIIB\nfQYKKwYBBAHWeQIEAgSCAW0EggFpAWcAdABOdaMnXJoQwzhbbNTfP1LrHfDgjhuN\nacCx+mSxYpo53wAAAY1b0vxkAAAEAwBFMEMCH0BRCgxPbBBVxhcWZ26a8JCe83P1\nJZ6wmv56GsVcyMACIDgpMbEo5HJITTRPnoyT4mG8cLrWjEvhchUdEcWUuk1TAHYA\nfVkeEuF4KnscYWd8Xv340IdcFKBOlZ65Ay/ZDowuebgAAAGNW9L8MAAABAMARzBF\nAiBdv5Z3pZFbfgoM3tGpCTM3ZxBMQsxBRSdTS6d8d2NAcwIhALLoCT9mTMN9OyFz\nIBV5MkXVLyuTf2OAzAOa7d8x2H6XAHcA5tIxY0B3jMEQQQbXcbnOwdJA9paEhvu6\nhzId/R43jlAAAAGNW9L8XwAABAMASDBGAiEA4Koh/VizdQU1tjZ2E2VGgWSXXkwn\nQmiYhmAeKcVLHeACIQD7JIGFsdGol7kss2pe4lYrCgPVc+iGZkuqnj26hqhr0TAN\nBgkqhkiG9w0BAQsFAAOCAQEABOFuAj4N4yNG9OOWNQWTNSICC4Rd4nOG1HRP/Bsn\nrz7KrcPORtb6D+Jx+Q0amhO31QhIvVBYs14gY4Ypyj7MzHgm4VmPXcqLvEkxb2G9\nQv9hYuEiNSQmm1fr5QAN/0AzbEbCM3cImLJ69kP5bUjfv/76KB57is8tYf9sh5ik\nLGKauxCM/zRIcGa3bXLDafk5S2g5Vr2hs230d/NGW1wZrE+zdGuMxfGJzJP+DAFv\niBfcQnFg4+1zMEKcqS87oniOyG+60RMM0MdejBD7AS43m9us96Gsun/4kufLQUTI\nFfnzxLutUV++3seshgefQOy5C/ayi8y1VTNmujPCxPCi6Q==\n-----END CERTIFICATE-----\n",
"-----BEGIN CERTIFICATE-----\nMIIEyDCCA7CgAwIBAgIQDPW9BitWAvR6uFAsI8zwZjANBgkqhkiG9w0BAQsFADBh\nMQswCQYDVQQGEwJVUzEVMBMGA1UEChMMRGlnaUNlcnQgSW5jMRkwFwYDVQQLExB3\nd3cuZGlnaWNlcnQuY29tMSAwHgYDVQQDExdEaWdpQ2VydCBHbG9iYWwgUm9vdCBH\nMjAeFw0yMTAzMzAwMDAwMDBaFw0zMTAzMjkyMzU5NTlaMFkxCzAJBgNVBAYTAlVT\nMRUwEwYDVQQKEwxEaWdpQ2VydCBJbmMxMzAxBgNVBAMTKkRpZ2lDZXJ0IEdsb2Jh\nbCBHMiBUTFMgUlNBIFNIQTI1NiAyMDIwIENBMTCCASIwDQYJKoZIhvcNAQEBBQAD\nggEPADCCAQoCggEBAMz3EGJPprtjb+2QUlbFbSd7ehJWivH0+dbn4Y+9lavyYEEV\ncNsSAPonCrVXOFt9slGTcZUOakGUWzUb+nv6u8W+JDD+Vu/E832X4xT1FE3LpxDy\nFuqrIvAxIhFhaZAmunjZlx/jfWardUSVc8is/+9dCopZQ+GssjoP80j812s3wWPc\n3kbW20X+fSP9kOhRBx5Ro1/tSUZUfyyIxfQTnJcVPAPooTncaQwywa8WV0yUR0J8\nosicfebUTVSvQpmowQTCd5zWSOTOEeAqgJnwQ3DPP3Zr0UxJqyRewg2C/Uaoq2yT\nzGJSQnWS+Jr6Xl6ysGHlHx+5fwmY6D36g39HaaECAwEAAaOCAYIwggF+MBIGA1Ud\nEwEB/wQIMAYBAf8CAQAwHQYDVR0OBBYEFHSFgMBmx9833s+9KTeqAx2+7c0XMB8G\nA1UdIwQYMBaAFE4iVCAYlebjbuYP+vq5Eu0GF485MA4GA1UdDwEB/wQEAwIBhjAd\nBgNVHSUEFjAUBggrBgEFBQcDAQYIKwYBBQUHAwIwdgYIKwYBBQUHAQEEajBoMCQG\nCCsGAQUFBzABhhhodHRwOi8vb2NzcC5kaWdpY2VydC5jb20wQAYIKwYBBQUHMAKG\nNGh0dHA6Ly9jYWNlcnRzLmRpZ2ljZXJ0LmNvbS9EaWdpQ2VydEdsb2JhbFJvb3RH\nMi5jcnQwQgYDVR0fBDswOTA3oDWgM4YxaHR0cDovL2NybDMuZGlnaWNlcnQuY29t\nL0RpZ2lDZXJ0R2xvYmFsUm9vdEcyLmNybDA9BgNVHSAENjA0MAsGCWCGSAGG/WwC\nATAHBgVngQwBATAIBgZngQwBAgEwCAYGZ4EMAQICMAgGBmeBDAECAzANBgkqhkiG\n9w0BAQsFAAOCAQEAkPFwyyiXaZd8dP3A+iZ7U6utzWX9upwGnIrXWkOH7U1MVl+t\nwcW1BSAuWdH/SvWgKtiwla3JLko716f2b4gp/DA/JIS7w7d7kwcsr4drdjPtAFVS\nslme5LnQ89/nD/7d+MS5EHKBCQRfz5eeLjJ1js+aWNJXMX43AYGyZm0pGrFmCW3R\nbpD0ufovARTFXFZkAdl9h6g4U5+LXUZtXMYnhIHUfoyMo5tS58aI7Dd8KvvwVVo4\nchDYABPPTHPbqjc1qCmBaZx2vN4Ye5DUys/vZwP9BFohFrH/6j/f3IL16/RZkiMN\nJCqVJUzKoZHm1Lesh3Sz8W2jmdv51b2EQJ8HmA==\n-----END CERTIFICATE-----\n"
],
"_chunks": [
{
"bytes": 648,
"inflated": 1256,
"ts": 234
}
],
"_connect_end": 93,
"_connect_ms": 33,
"_connect_start": 60,
"_contentEncoding": "gzip",
"_contentType": "text/html",
"_created": 8,
"_dns_end": 60,
"_dns_info": {
"results": {
"aliases": [
"www.example.com"
],
"canonical_names": [
"www.example.com"
],
"endpoint_metadatas": [],
"expiration": "13370780176732624",
"host_ports": [],
"hostname_results": [],
"ip_endpoints": [
{
"endpoint_address": "93.184.215.14",
"endpoint_port": 0
}
],
"text_records": []
},
"secure": false,
"transactions_needed": [
{
"dns_query_type": "A"
},
{
"dns_query_type": "HTTPS"
}
]
},
"_dns_ms": 59,
"_dns_start": 1,
"_documentURL": "https://www.example.com/",
"_download_end": 234,
"_download_ms": 2,
"_download_start": 232,
"_expires": "Sun, 22 Sep 2024 03:21:43 GMT",
"_final_base_page": true,
"_frame_id": "E021D0149DE3689992ECE4DF4B0ECA38",
"_full_url": "https://www.example.com/",
"_gzip_save": 0,
"_gzip_total": 648,
"_host": "www.example.com",
"_http2_server_settings": {
"SETTINGS_DEPRECATE_HTTP2_PRIORITIES": 0,
"SETTINGS_ENABLE_PUSH": 0,
"SETTINGS_HEADER_TABLE_SIZE": 4096,
"SETTINGS_INITIAL_WINDOW_SIZE": 1048576,
"SETTINGS_MAX_CONCURRENT_STREAMS": 100,
"SETTINGS_MAX_FRAME_SIZE": 16384,
"SETTINGS_MAX_HEADER_LIST_SIZE": 16384
},
"_http2_stream_dependency": 0,
"_http2_stream_exclusive": 1,
"_http2_stream_id": 1,
"_http2_stream_weight": 256,
"_id": "44714C6F6C72B045136D19CA9894886A",
"_image_save": null,
"_image_total": null,
"_index": 0,
"_initial_priority": "Highest",
"_initiator": "",
"_initiator_column": "",
"_initiator_line": "",
"_initiator_type": "script",
"_ip_addr": "93.184.215.14",
"_is_base_page": true,
"_is_secure": 1,
"_load_end": 234,
"_load_ms": 43,
"_load_start": 191,
"_load_start_float": 191.000079,
"_method": "GET",
"_minify_save": null,
"_minify_total": null,
"_netlog_id": 79,
"_number": 1,
"_objectSize": 648,
"_objectSizeUncompressed": 1256,
"_priority": "Highest",
"_protocol": "HTTP/2",
"_raw_id": "44714C6F6C72B045136D19CA9894886A",
"_request_id": "44714C6F6C72B045136D19CA9894886A",
"_request_type": "Document",
"_responseCode": 200,
"_run": 1,
"_score_cache": -1,
"_score_cdn": 100,
"_score_combine": -1,
"_score_compress": -1,
"_score_cookies": -1,
"_score_etags": -1,
"_score_gzip": 100,
"_score_keep-alive": 100,
"_score_minify": -1,
"_securityDetails": {
"certificateId": 0,
"certificateTransparencyCompliance": "compliant",
"cipher": "AES_256_GCM",
"encryptedClientHello": false,
"issuer": "DigiCert Global G2 TLS RSA SHA256 2020 CA1",
"keyExchange": "",
"keyExchangeGroup": "P-256",
"protocol": "TLS 1.3",
"sanList": [
"www.example.org",
"example.net",
"example.edu",
"example.com",
"example.org",
"www.example.com",
"www.example.edu",
"www.example.net"
],
"serverSignatureAlgorithm": 2052,
"signedCertificateTimestampList": [
{
"hashAlgorithm": "SHA-256",
"logDescription": "Google 'Argon2025h1' log",
"logId": "4E75A3275C9A10C3385B6CD4DF3F52EB1DF0E08E1B8D69C0B1FA64B1629A39DF",
"origin": "Embedded in certificate",
"signatureAlgorithm": "ECDSA",
"signatureData": "3043021F40510A0C4F6C1055C61716676E9AF0909EF373F5259EB09AFE7A1AC55CC8C00220382931B128E472484D344F9E8C93E261BC70BAD68C4BE172151D11C594BA4D53",
"status": "Verified",
"timestamp": 1706642570340
},
{
"hashAlgorithm": "SHA-256",
"logDescription": "DigiCert Yeti2025 Log",
"logId": "7D591E12E1782A7B1C61677C5EFDF8D0875C14A04E959EB9032FD90E8C2E79B8",
"origin": "Embedded in certificate",
"signatureAlgorithm": "ECDSA",
"signatureData": "304502205DBF9677A5915B7E0A0CDED1A909333767104C42CC414527534BA77C77634073022100B2E8093F664CC37D3B21732015793245D52F2B937F6380CC039AEDDF31D87E97",
"status": "Verified",
"timestamp": 1706642570288
},
{
"hashAlgorithm": "SHA-256",
"logDescription": "DigiCert Nessie2025 Log",
"logId": "E6D2316340778CC1104106D771B9CEC1D240F6968486FBBA87321DFD1E378E50",
"origin": "Embedded in certificate",
"signatureAlgorithm": "ECDSA",
"signatureData": "3046022100E0AA21FD58B3750535B636761365468164975E4C2742689886601E29C54B1DE0022100FB248185B1D1A897B92CB36A5EE2562B0A03D573E886664BAA9E3DBA86A86BD1",
"status": "Verified",
"timestamp": 1706642570335
}
],
"subjectName": "www.example.org",
"validFrom": 1706572800,
"validTo": 1740873599
},
"_server_count": null,
"_server_port": "443",
"_server_rtt": null,
"_socket": 86,
"_socket_group": "https://www.example.com ",
"_ssl_end": 191,
"_ssl_ms": 98,
"_ssl_start": 93,
"_tls_cipher_suite": 4866,
"_tls_next_proto": "h2",
"_tls_resumed": "False",
"_tls_version": "TLS 1.3",
"_ttfb_end": 232,
"_ttfb_ms": 41,
"_ttfb_start": 191,
"_type": 3,
"_url": "/",
"cache": {},
"pageref": "page_1_0_1",
"request": {
"bodySize": -1,
"cookies": [],
"headersSize": 683,
"httpVersion": "HTTP/2",
"method": "GET",
"queryString": [],
"url": "https://www.example.com/"
},
"response": {
"bodySize": 648,
"content": {
"mimeType": "text/html",
"size": 648
},
"cookies": [],
"headersSize": 376,
"httpVersion": "HTTP/2",
"status": 200,
"statusText": ""
},
"startedDateTime": "2024-09-15T03:21:43.105962",
"time": 285,
"timings": {
"blocked": 52,
"connect": 131,
"dns": 59,
"receive": 2,
"send": 0,
"ssl": 98,
"wait": 41
}
}
```
## Schema
[Section titled “Schema”](#schema)
### `_all_end`
[Section titled “\_all\_end”](#_all_end)
Type: `int`
End time of all operations.
### `_all_ms`
[Section titled “\_all\_ms”](#_all_ms)
Type: `int`
Total time taken for all operations.
### `_all_start`
[Section titled “\_all\_start”](#_all_start)
Type: `int`
Start time of all operations.
### `_body_file`
[Section titled “\_body\_file”](#_body_file)
Type: `string`
File containing the body of the request.
### `_bytesIn`
[Section titled “\_bytesIn”](#_bytesin)
Type: `int`
Number of bytes received.
### `_bytesOut`
[Section titled “\_bytesOut”](#_bytesout)
Type: `int`
Number of bytes sent.
### `_cacheControl`
[Section titled “\_cacheControl”](#_cachecontrol)
Type: `string`
Cache control header value.
### `_cache_time`
[Section titled “\_cache\_time”](#_cache_time)
Type: `int`
Cache time.
### `_cached`
[Section titled “\_cached”](#_cached)
Type: `int`
Indicates if the request was cached (0 or 1).
### `_cdn_provider`
[Section titled “\_cdn\_provider”](#_cdn_provider)
Type: `string`
CDN provider used.
### `_certificates`
[Section titled “\_certificates”](#_certificates)
Type: `array`
Certificates used.
### `_chunks`
[Section titled “\_chunks”](#_chunks)
Type: `array`
Array of chunks received.
* #### `_chunks[].bytes`
[Section titled “\_chunks\[\].bytes”](#_chunksbytes)
Type: `int`
Size of the chunk.
* #### `_chunks[].inflated`
[Section titled “\_chunks\[\].inflated”](#_chunksinflated)
Type: `int`
Size of the inflated chunk.
* #### `_chunks[].ts`
[Section titled “\_chunks\[\].ts”](#_chunksts)
Type: `int`
Timestamp of the chunk.
### `_connect_end`
[Section titled “\_connect\_end”](#_connect_end)
Type: `int`
Connection end time.
### `_connect_ms`
[Section titled “\_connect\_ms”](#_connect_ms)
Type: `int`
Connection time in milliseconds.
### `_connect_start`
[Section titled “\_connect\_start”](#_connect_start)
Type: `int`
Connection start time.
### `_contentEncoding`
[Section titled “\_contentEncoding”](#_contentencoding)
Type: `string`
Content encoding of the response.
### `_contentType`
[Section titled “\_contentType”](#_contenttype)
Type: `string`
Content type of the response.
### `_created`
[Section titled “\_created”](#_created)
Type: `int`
Creation time of the request.
### `_dns_end`
[Section titled “\_dns\_end”](#_dns_end)
Type: `int`
DNS end time.
### `_dns_info`
[Section titled “\_dns\_info”](#_dns_info)
Type: `object`
DNS information.
* #### `_dns_info.results`
[Section titled “\_dns\_info.results”](#_dns_inforesults)
Type: `object`
Results of the DNS query.
* #### `_dns_info.results.aliases`
[Section titled “\_dns\_info.results.aliases”](#_dns_inforesultsaliases)
Type: `array`
Aliases for the domain.
* #### `_dns_info.results.canonical_names`
[Section titled “\_dns\_info.results.canonical\_names”](#_dns_inforesultscanonical_names)
Type: `array`
Canonical names for the domain.
* #### `_dns_info.results.endpoint_metadatas`
[Section titled “\_dns\_info.results.endpoint\_metadatas”](#_dns_inforesultsendpoint_metadatas)
Type: `array`
Endpoint metadata.
* #### `_dns_info.results.expiration`
[Section titled “\_dns\_info.results.expiration”](#_dns_inforesultsexpiration)
Type: `string`
Expiration date of the DNS query.
* #### `_dns_info.results.host_ports`
[Section titled “\_dns\_info.results.host\_ports”](#_dns_inforesultshost_ports)
Type: `array`
Host ports.
* #### `_dns_info.results.hostname_results`
[Section titled “\_dns\_info.results.hostname\_results”](#_dns_inforesultshostname_results)
Type: `array`
Hostname results.
* #### `_dns_info.results.ip_endpoints`
[Section titled “\_dns\_info.results.ip\_endpoints”](#_dns_inforesultsip_endpoints)
Type: `array`
IP endpoints.
* #### `_dns_info.results.ip_endpoints[].endpoint_address`
[Section titled “\_dns\_info.results.ip\_endpoints\[\].endpoint\_address”](#_dns_inforesultsip_endpointsendpoint_address)
Type: `string`
IP address of the endpoint.
* #### `_dns_info.results.ip_endpoints[].endpoint_port`
[Section titled “\_dns\_info.results.ip\_endpoints\[\].endpoint\_port”](#_dns_inforesultsip_endpointsendpoint_port)
Type: `int`
Port of the endpoint.
* #### `_dns_info.results.text_records`
[Section titled “\_dns\_info.results.text\_records”](#_dns_inforesultstext_records)
Type: `array`
Text records.
* #### `_dns_info.secure`
[Section titled “\_dns\_info.secure”](#_dns_infosecure)
Type: `int`
Indicates if the DNS query is secure.
* #### `_dns_info.transactions_needed`
[Section titled “\_dns\_info.transactions\_needed”](#_dns_infotransactions_needed)
Type: `array`
Transactions needed for DNS query.
* #### `_dns_info.transactions_needed[].dns_query_type`
[Section titled “\_dns\_info.transactions\_needed\[\].dns\_query\_type”](#_dns_infotransactions_neededdns_query_type)
Type: `string`
Type of DNS query.
### `_dns_ms`
[Section titled “\_dns\_ms”](#_dns_ms)
Type: `int`
DNS lookup time in milliseconds.
### `_dns_start`
[Section titled “\_dns\_start”](#_dns_start)
Type: `int`
DNS start time.
### `_documentURL`
[Section titled “\_documentURL”](#_documenturl)
Type: `string`
Document URL of the request.
### `_download_end`
[Section titled “\_download\_end”](#_download_end)
Type: `int`
Download end time.
### `_download_ms`
[Section titled “\_download\_ms”](#_download_ms)
Type: `int`
Download time in milliseconds.
### `_download_start`
[Section titled “\_download\_start”](#_download_start)
Type: `int`
Download start time.
### `_expires`
[Section titled “\_expires”](#_expires)
Type: `string`
Expiry date of the request.
### `_final_base_page`
[Section titled “\_final\_base\_page”](#_final_base_page)
Type: `int`
Indicates if the request is the final base page.
### `_frame_id`
[Section titled “\_frame\_id”](#_frame_id)
Type: `string`
Frame ID where the request was made.
### `_full_url`
[Section titled “\_full\_url”](#_full_url)
Type: `string`
Full URL of the request.
### `_gzip_save`
[Section titled “\_gzip\_save”](#_gzip_save)
Type: `int`
Size saved due to gzip compression.
### `_gzip_total`
[Section titled “\_gzip\_total”](#_gzip_total)
Type: `int`
Total size of the gzip-compressed content.
### `_host`
[Section titled “\_host”](#_host)
Type: `string`
Host of the request.
### `_http2_server_settings`
[Section titled “\_http2\_server\_settings”](#_http2_server_settings)
Type: `object`
HTTP/2 server settings.
### `_http2_stream_dependency`
[Section titled “\_http2\_stream\_dependency”](#_http2_stream_dependency)
Type: `int`
HTTP/2 stream dependency.
### `_http2_stream_exclusive`
[Section titled “\_http2\_stream\_exclusive”](#_http2_stream_exclusive)
Type: `int`
HTTP/2 stream exclusivity.
### `_http2_stream_id`
[Section titled “\_http2\_stream\_id”](#_http2_stream_id)
Type: `int`
HTTP/2 stream ID.
### `_http2_stream_weight`
[Section titled “\_http2\_stream\_weight”](#_http2_stream_weight)
Type: `int`
HTTP/2 stream weight.
### `_id`
[Section titled “\_id”](#_id)
Type: `string`
Unique identifier for the request.
### `_image_save`
[Section titled “\_image\_save”](#_image_save)
Type: `int`
Size saved due to image optimization.
### `_image_total`
[Section titled “\_image\_total”](#_image_total)
Type: `int`
Total size of images.
### `_index`
[Section titled “\_index”](#_index)
Type: `int`
Index of the request.
### `_initial_priority`
[Section titled “\_initial\_priority”](#_initial_priority)
Type: `string`
Initial priority of the request.
### `_initiator`
[Section titled “\_initiator”](#_initiator)
Type: `string`
Initiator of the request.
### `_initiator_column`
[Section titled “\_initiator\_column”](#_initiator_column)
Type: `string`
Column number of the initiator.
### `_initiator_line`
[Section titled “\_initiator\_line”](#_initiator_line)
Type: `string`
Line number of the initiator.
### `_initiator_type`
[Section titled “\_initiator\_type”](#_initiator_type)
Type: `string`
Type of initiator (e.g., script).
### `_ip_addr`
[Section titled “\_ip\_addr”](#_ip_addr)
Type: `string`
IP address of the requested server.
### `_is_base_page`
[Section titled “\_is\_base\_page”](#_is_base_page)
Type: `int`
Indicates if the request is the base page.
### `_is_secure`
[Section titled “\_is\_secure”](#_is_secure)
Type: `int`
Indicates if the request is secure (0 or 1).
### `_load_end`
[Section titled “\_load\_end”](#_load_end)
Type: `int`
Load end time.
### `_load_ms`
[Section titled “\_load\_ms”](#_load_ms)
Type: `int`
Load time in milliseconds.
### `_load_start`
[Section titled “\_load\_start”](#_load_start)
Type: `int`
Start time of load in milliseconds.
### `_load_start_float`
[Section titled “\_load\_start\_float”](#_load_start_float)
Type: `float`
Precise start time of load.
### `_method`
[Section titled “\_method”](#_method)
Type: `string`
HTTP method used for the request.
### `_minify_save`
[Section titled “\_minify\_save”](#_minify_save)
Type: `int`
Size saved due to minification.
### `_minify_total`
[Section titled “\_minify\_total”](#_minify_total)
Type: `int`
Total size of minified content.
### `_netlog_id`
[Section titled “\_netlog\_id”](#_netlog_id)
Type: `int`
Netlog ID.
### `_number`
[Section titled “\_number”](#_number)
Type: `int`
Number of the request.
### `_objectSize`
[Section titled “\_objectSize”](#_objectsize)
Type: `int`
Size of the object received.
### `_objectSizeUncompressed`
[Section titled “\_objectSizeUncompressed”](#_objectsizeuncompressed)
Type: `int`
Uncompressed size of the object received.
### `_priority`
[Section titled “\_priority”](#_priority)
Type: `string`
Priority of the request.
### `_protocol`
[Section titled “\_protocol”](#_protocol)
Type: `string`
Protocol used for the request.
### `_raw_id`
[Section titled “\_raw\_id”](#_raw_id)
Type: `string`
Raw ID for the request.
### `_request_id`
[Section titled “\_request\_id”](#_request_id)
Type: `string`
Identifier for the original request.
### `_request_type`
[Section titled “\_request\_type”](#_request_type)
Type: `string`
Type of the request (e.g., Document).
### `_responseCode`
[Section titled “\_responseCode”](#_responsecode)
Type: `int`
HTTP response code.
### `_run`
[Section titled “\_run”](#_run)
Type: `int`
The run number of the test.
### `_score_cache`
[Section titled “\_score\_cache”](#_score_cache)
Type: `int`
Cache score.
### `_score_cdn`
[Section titled “\_score\_cdn”](#_score_cdn)
Type: `int`
CDN score.
### `_score_combine`
[Section titled “\_score\_combine”](#_score_combine)
Type: `int`
Combine score.
### `_score_compress`
[Section titled “\_score\_compress”](#_score_compress)
Type: `int`
Compression score.
### `_score_cookies`
[Section titled “\_score\_cookies”](#_score_cookies)
Type: `int`
Cookies score.
### `_score_etags`
[Section titled “\_score\_etags”](#_score_etags)
Type: `int`
ETags score.
### `_score_gzip`
[Section titled “\_score\_gzip”](#_score_gzip)
Type: `int`
Gzip compression score.
### `_score_keep-alive`
[Section titled “\_score\_keep-alive”](#_score_keep-alive)
Type: `int`
Keep-alive score.
### `_score_minify`
[Section titled “\_score\_minify”](#_score_minify)
Type: `int`
Minification score.
### `_securityDetails`
[Section titled “\_securityDetails”](#_securitydetails)
Type: `object`
Security details of the request.
* #### `_securityDetails.certificateId`
[Section titled “\_securityDetails.certificateId”](#_securitydetailscertificateid)
Type: `int`
Certificate ID.
* #### `_securityDetails.certificateTransparencyCompliance`
[Section titled “\_securityDetails.certificateTransparencyCompliance”](#_securitydetailscertificatetransparencycompliance)
Type: `string`
Certificate transparency compliance.
* #### `_securityDetails.cipher`
[Section titled “\_securityDetails.cipher”](#_securitydetailscipher)
Type: `string`
Cipher used.
* #### `_securityDetails.encryptedClientHello`
[Section titled “\_securityDetails.encryptedClientHello”](#_securitydetailsencryptedclienthello)
Type: `int`
Indicates if the client hello is encrypted.
* #### `_securityDetails.issuer`
[Section titled “\_securityDetails.issuer”](#_securitydetailsissuer)
Type: `string`
Issuer of the certificate.
* #### `_securityDetails.keyExchange`
[Section titled “\_securityDetails.keyExchange”](#_securitydetailskeyexchange)
Type: `string`
Key exchange used.
* #### `_securityDetails.keyExchangeGroup`
[Section titled “\_securityDetails.keyExchangeGroup”](#_securitydetailskeyexchangegroup)
Type: `string`
Key exchange group used.
* #### `_securityDetails.protocol`
[Section titled “\_securityDetails.protocol”](#_securitydetailsprotocol)
Type: `string`
Security protocol used.
* #### `_securityDetails.sanList`
[Section titled “\_securityDetails.sanList”](#_securitydetailssanlist)
Type: `array`
Subject alternative names.
* #### `_securityDetails.serverSignatureAlgorithm`
[Section titled “\_securityDetails.serverSignatureAlgorithm”](#_securitydetailsserversignaturealgorithm)
Type: `int`
Server signature algorithm.
* #### `_securityDetails.signedCertificateTimestampList`
[Section titled “\_securityDetails.signedCertificateTimestampList”](#_securitydetailssignedcertificatetimestamplist)
Type: `array`
List of signed certificate timestamps.
* #### `_securityDetails.subjectName`
[Section titled “\_securityDetails.subjectName”](#_securitydetailssubjectname)
Type: `string`
Subject name of the certificate.
* #### `_securityDetails.validFrom`
[Section titled “\_securityDetails.validFrom”](#_securitydetailsvalidfrom)
Type: `int`
Valid from date of the certificate.
* #### `_securityDetails.validTo`
[Section titled “\_securityDetails.validTo”](#_securitydetailsvalidto)
Type: `int`
Valid to date of the certificate.
### `_server_count`
[Section titled “\_server\_count”](#_server_count)
Type: `int`
Number of servers used.
### `_server_port`
[Section titled “\_server\_port”](#_server_port)
Type: `string`
Server port.
### `_server_rtt`
[Section titled “\_server\_rtt”](#_server_rtt)
Type: `int`
Server round-trip time.
### `_socket`
[Section titled “\_socket”](#_socket)
Type: `int`
Socket used for the request.
### `_socket_group`
[Section titled “\_socket\_group”](#_socket_group)
Type: `string`
Socket group.
### `_ssl_end`
[Section titled “\_ssl\_end”](#_ssl_end)
Type: `int`
SSL handshake end time.
### `_ssl_ms`
[Section titled “\_ssl\_ms”](#_ssl_ms)
Type: `int`
SSL handshake time in milliseconds.
### `_ssl_start`
[Section titled “\_ssl\_start”](#_ssl_start)
Type: `int`
SSL handshake start time.
### `_tls_cipher_suite`
[Section titled “\_tls\_cipher\_suite”](#_tls_cipher_suite)
Type: `int`
Cipher suite used.
### `_tls_next_proto`
[Section titled “\_tls\_next\_proto”](#_tls_next_proto)
Type: `string`
Next protocol used.
### `_tls_resumed`
[Section titled “\_tls\_resumed”](#_tls_resumed)
Type: `string`
Indicates if the TLS session was resumed.
### `_tls_version`
[Section titled “\_tls\_version”](#_tls_version)
Type: `string`
TLS version used.
### `_ttfb_end`
[Section titled “\_ttfb\_end”](#_ttfb_end)
Type: `int`
Time to first byte end time.
### `_ttfb_ms`
[Section titled “\_ttfb\_ms”](#_ttfb_ms)
Type: `int`
Time to first byte in milliseconds.
### `_ttfb_start`
[Section titled “\_ttfb\_start”](#_ttfb_start)
Type: `int`
Time to first byte start time.
### `_type`
[Section titled “\_type”](#_type)
Type: `int`
Type identifier for the request.
### `_url`
[Section titled “\_url”](#_url)
Type: `string`
URL path of the request.
### `cache`
[Section titled “cache”](#cache)
Type: `object`
Cache details (empty in this example).
### `pageref`
[Section titled “pageref”](#pageref)
Type: `string`
Reference to the page containing this request.
### `request`
[Section titled “request”](#request)
Type: `object`
Details of the request.
* #### `request.bodySize`
[Section titled “request.bodySize”](#requestbodysize)
Type: `int`
Size of the request body.
* #### `request.cookies`
[Section titled “request.cookies”](#requestcookies)
Type: `array`
Cookies sent with the request.
* #### `request.headersSize`
[Section titled “request.headersSize”](#requestheaderssize)
Type: `int`
Size of the request headers.
* #### `request.httpVersion`
[Section titled “request.httpVersion”](#requesthttpversion)
Type: `string`
HTTP version used for the request.
* #### `request.method`
[Section titled “request.method”](#requestmethod)
Type: `string`
HTTP method used for the request.
* #### `request.queryString`
[Section titled “request.queryString”](#requestquerystring)
Type: `array`
Query string parameters.
* #### `request.url`
[Section titled “request.url”](#requesturl)
Type: `string`
URL of the requested resource.
### `response`
[Section titled “response”](#response)
Type: `object`
Details of the response.
* #### `response.bodySize`
[Section titled “response.bodySize”](#responsebodysize)
Type: `int`
Size of the response body.
* #### `response.content`
[Section titled “response.content”](#responsecontent)
Type: `object`
Content details of the response.
* #### `response.content.mimeType`
[Section titled “response.content.mimeType”](#responsecontentmimetype)
Type: `string`
MIME type of the content.
* #### `response.content.size`
[Section titled “response.content.size”](#responsecontentsize)
Type: `int`
Size of the content.
* #### `response.cookies`
[Section titled “response.cookies”](#responsecookies)
Type: `array`
Cookies received with the response.
* #### `response.headersSize`
[Section titled “response.headersSize”](#responseheaderssize)
Type: `int`
Size of the response headers.
* #### `response.httpVersion`
[Section titled “response.httpVersion”](#responsehttpversion)
Type: `string`
HTTP version used for the response.
* #### `response.status`
[Section titled “response.status”](#responsestatus)
Type: `int`
HTTP response status code.
* #### `response.statusText`
[Section titled “response.statusText”](#responsestatustext)
Type: `string`
Status text of the response.
### `startedDateTime`
[Section titled “startedDateTime”](#starteddatetime)
Type: `string`
Start time of the request.
### `time`
[Section titled “time”](#time)
Type: `int`
Total time taken for the request in milliseconds.
### `timings`
[Section titled “timings”](#timings)
Type: `object`
Timing details of various stages of the request.
* #### `timings.blocked`
[Section titled “timings.blocked”](#timingsblocked)
Type: `int`
Time spent in blocking.
* #### `timings.connect`
[Section titled “timings.connect”](#timingsconnect)
Type: `int`
Time spent in establishing a connection.
* #### `timings.dns`
[Section titled “timings.dns”](#timingsdns)
Type: `int`
Time spent in DNS lookup.
* #### `timings.receive`
[Section titled “timings.receive”](#timingsreceive)
Type: `int`
Time spent in receiving the response.
* #### `timings.send`
[Section titled “timings.send”](#timingssend)
Type: `int`
Time spent in sending the request.
* #### `timings.ssl`
[Section titled “timings.ssl”](#timingsssl)
Type: `int`
Time spent in SSL handshake.
* #### `timings.wait`
[Section titled “timings.wait”](#timingswait)
Type: `int`
Time spent in waiting for the response.
# Request summary blob
> Reference docs for the request summary blob
*Appears in: [`requests`](/reference/tables/requests/) table*\
*As: [`summary`](/reference/tables/requests/#summary)*
JSON-encoded summarization of request data.
An example of the decoded object
```json
{
"_cdn_provider": "Edgecast",
"_gzip_save": 0,
"expAge": 604800,
"ext": "",
"format": "",
"method": "GET",
"mimeType": "text/html",
"redirectUrl": null,
"reqBodySize": null,
"reqCookieLen": 0,
"reqHeadersSize": 683,
"respBodySize": 648,
"respCookieLen": 0,
"respHeadersSize": 376,
"respHttpVersion": "HTTP/2",
"respSize": 648,
"status": 200,
"time": 285,
"type": "html"
}
```
## Schema
[Section titled “Schema”](#schema)
### `time`
[Section titled “time”](#time)
The total time taken for the request in milliseconds.
### `_cdn_provider`
[Section titled “\_cdn\_provider”](#_cdn_provider)
The Content Delivery Network provider.
### `_gzip_save`
[Section titled “\_gzip\_save”](#_gzip_save)
Bytes saved due to gzip compression.
### `method`
[Section titled “method”](#method)
The HTTP method used for the request (e.g., “GET”, “POST”).
### `reqHeadersSize`
[Section titled “reqHeadersSize”](#reqheaderssize)
The size of the request headers in bytes.
### `reqBodySize`
[Section titled “reqBodySize”](#reqbodysize)
The size of the request body in bytes.
### `reqCookieLen`
[Section titled “reqCookieLen”](#reqcookielen)
The length of the request cookies.
### `status`
[Section titled “status”](#status)
The HTTP status code of the response.
### `respHttpVersion`
[Section titled “respHttpVersion”](#resphttpversion)
The HTTP version used in the response.
### `redirectUrl`
[Section titled “redirectUrl”](#redirecturl)
The URL to which the request was redirected.
### `respHeadersSize`
[Section titled “respHeadersSize”](#respheaderssize)
The size of the response headers in bytes.
### `respBodySize`
[Section titled “respBodySize”](#respbodysize)
The size of the response body in bytes.
### `respSize`
[Section titled “respSize”](#respsize)
The total size of the response in bytes.
### `mimeType`
[Section titled “mimeType”](#mimetype)
The MIME type of the response.
### `ext`
[Section titled “ext”](#ext)
The file extension of the requested resource.
### `format`
[Section titled “format”](#format)
The format of the resource.
### `respCookieLen`
[Section titled “respCookieLen”](#respcookielen)
The length of the response cookies.
### `expAge`
[Section titled “expAge”](#expage)
The age of the cached response in seconds.
# Other custom metric
> Reference docs for the other custom metric
*Appears in: [`custom_metrics`](/reference/structs/custom-metrics/) struct*\
*As: [`other`](/reference/structs/custom-metrics/#other)*
## Schema
[Section titled “Schema”](#schema)
### `ads`
[Section titled “ads”](#ads)
Advertising technology and usage. See the [ads](/reference/custom-metrics/other/ads/) custom metric for more information.
### `almanac`
[Section titled “almanac”](#almanac)
Metrics defined in the early versions of Web Almanac crawls.
### `aurora`
[Section titled “aurora”](#aurora)
Project Aurora.
### `avg_dom_depth`
[Section titled “avg\_dom\_depth”](#avg_dom_depth)
The average DOM depth of a page.
### `Colordepth`
[Section titled “Colordepth”](#colordepth)
Color depth of a screen.
### `crawl_links`
[Section titled “crawl\_links”](#crawl_links)
The links found during a crawl.
### `css`
[Section titled “css”](#css)
CSS usage.
### `doctype`
[Section titled “doctype”](#doctype)
Document type declaration.
### `document_height`
[Section titled “document\_height”](#document_height)
Height of the document.
### `document_width`
[Section titled “document\_width”](#document_width)
Width of the document.
### `Dpi`
[Section titled “Dpi”](#dpi)
Dots per inch (DPI) of a screen.
### `event-names`
[Section titled “event-names”](#event-names)
Event names used in JavaScript.
### `fugu-apis`
[Section titled “fugu-apis”](#fugu-apis)
Usage of Fugu APIs.
### `generated-content`
[Section titled “generated-content”](#generated-content)
Client-side generated content.
### `has_shadow_root`
[Section titled “has\_shadow\_root”](#has_shadow_root)
Presence of shadow DOM roots.
### `Images`
[Section titled “Images”](#images)
Images usage.
### `img-loading-attr`
[Section titled “img-loading-attr”](#img-loading-attr)
Image loading attributes.
### `initiators`
[Section titled “initiators”](#initiators)
Resource initiators.
### `inline_style_bytes`
[Section titled “inline\_style\_bytes”](#inline_style_bytes)
Type: `integer`
Size of inline styles.
### `lib-detector-version`
[Section titled “lib-detector-version”](#lib-detector-version)
Libraries detector version.
### `localstorage_size`
[Section titled “localstorage\_size”](#localstorage_size)
Size of local storage.
### `meta_viewport`
[Section titled “meta\_viewport”](#meta_viewport)
Meta viewport tag.
### `num_iframes`
[Section titled “num\_iframes”](#num_iframes)
Type: `integer`
Number of iframes on a page.
### `num_scripts`
[Section titled “num\_scripts”](#num_scripts)
Type: `integer`
Number of script tags.
### `num_scripts_async`
[Section titled “num\_scripts\_async”](#num_scripts_async)
Type: `integer`
Number of asynchronous scripts.
### `num_scripts_sync`
[Section titled “num\_scripts\_sync”](#num_scripts_sync)
Type: `integer`
Number of synchronous scripts.
### `observers`
[Section titled “observers”](#observers)
Metrics related to the usage of observer APIs.
### `privacy-sandbox`
[Section titled “privacy-sandbox”](#privacy-sandbox)
Privacy Sandbox initiative usage.
### `pwa`
[Section titled “pwa”](#pwa)
Progressive Web Apps.
### `quirks_mode`
[Section titled “quirks\_mode”](#quirks_mode)
Usage of quirks mode in browsers.
### `Resolution`
[Section titled “Resolution”](#resolution)
Resolution of a screen.
### `robots_meta`
[Section titled “robots\_meta”](#robots_meta)
Robots meta tag.
### `sass`
[Section titled “sass”](#sass)
Usage of Sass.
### `sessionstorage_size`
[Section titled “sessionstorage\_size”](#sessionstorage_size)
Size of session storage.
### `usertiming`
[Section titled “usertiming”](#usertiming)
User Timing API.
### `valid-head`
[Section titled “valid-head”](#valid-head)
Validity of the head element.
# Ads custom metric
> Reference docs for the ads custom metric
*Appears in: [`custom_metrics.other`](/reference/custom-metrics/other/) struct*\
*As: [`ads`](/reference/custom-metrics/other/#ads)*
## Schema
[Section titled “Schema”](#schema)
### `ads`
[Section titled “ads”](#ads)
Type: `object`
Contains information about the ads.txt file. See [IAB Ads.txt Specification](https://github.com/InteractiveAdvertisingBureau/Supply-Chain-Validation/blob/main/ads.txt%20v1.1.md).
#### `ads.present`
[Section titled “ads.present”](#adspresent)
Type: `boolean`
Indicates if the ads.txt or app-ads.txt file is present.
#### `ads.status`
[Section titled “ads.status”](#adsstatus)
Type: `integer`
HTTP status code of the ads.txt file response.
#### `ads.redirected`
[Section titled “ads.redirected”](#adsredirected)
Type: `boolean`
Indicates if the ads.txt file request was redirected.
#### `ads.redirected_to`
[Section titled “ads.redirected\_to”](#adsredirected_to)
Type: `string`
URL to which the ads.txt resource was redirected.
#### `ads.account_count`
[Section titled “ads.account\_count”](#adsaccount_count)
Type: `integer`
Number of advertising accounts listed in the ads.txt file.
#### `ads.account_types`
[Section titled “ads.account\_types”](#adsaccount_types)
Type: `object`
Types of accounts (direct or reseller) listed in the ads.txt file.
##### `ads.account_types.direct`
[Section titled “ads.account\_types.direct”](#adsaccount_typesdirect)
Type: `object`
Information about direct advertising accounts.
###### `ads.account_types.direct.domains`
[Section titled “ads.account\_types.direct.domains”](#adsaccount_typesdirectdomains)
Type: `array`
List of domains with advertising accounts of this type.
###### `ads.account_types.direct.account_count`
[Section titled “ads.account\_types.direct.account\_count”](#adsaccount_typesdirectaccount_count)
Type: `integer`
Number of advertising accounts of this type.
###### `ads.account_types.direct.domain_count`
[Section titled “ads.account\_types.direct.domain\_count”](#adsaccount_typesdirectdomain_count)
Type: `integer`
Number of unique domains with advertising accounts of this type.
##### `ads.account_types.reseller`
[Section titled “ads.account\_types.reseller”](#adsaccount_typesreseller)
Type: `object`
Information about reseller advertising accounts.
###### `ads.account_types.reseller.domains`
[Section titled “ads.account\_types.reseller.domains”](#adsaccount_typesresellerdomains)
Type: `array`
List of domains with advertising accounts of this type.
###### `ads.account_types.reseller.account_count`
[Section titled “ads.account\_types.reseller.account\_count”](#adsaccount_typesreselleraccount_count)
Type: `integer`
Number of advertising accounts of this type.
###### `ads.account_types.reseller.domain_count`
[Section titled “ads.account\_types.reseller.domain\_count”](#adsaccount_typesresellerdomain_count)
Type: `integer`
Number of unique domains with advertising accounts of this type.
#### `ads.line_count`
[Section titled “ads.line\_count”](#adsline_count)
Type: `integer`
Total number of lines in the ads.txt file.
#### `ads.variables`
[Section titled “ads.variables”](#adsvariables)
Type: `array`
List of variables found in the ads.txt file.
#### `ads.variable_count`
[Section titled “ads.variable\_count”](#adsvariable_count)
Type: `integer`
Number of variables found in the ads.txt file.
#### `ads.error`
[Section titled “ads.error”](#adserror)
Type: `string`
Error message if fetch or parse failed.
### `app_ads`
[Section titled “app\_ads”](#app_ads)
Type: `object`
Contains information about the app-ads.txt file. See [IAB App-Ads.txt Specification](https://github.com/InteractiveAdvertisingBureau/Supply-Chain-Validation/blob/main/app-ads.txt.md).
#### `app_ads.present`
[Section titled “app\_ads.present”](#app_adspresent)
Type: `boolean`
Indicates if the ads.txt or app-ads.txt file is present.
#### `app_ads.status`
[Section titled “app\_ads.status”](#app_adsstatus)
Type: `integer`
HTTP status code of the ads.txt file response.
#### `app_ads.redirected`
[Section titled “app\_ads.redirected”](#app_adsredirected)
Type: `boolean`
Indicates if the ads.txt file request was redirected.
#### `app_ads.redirected_to`
[Section titled “app\_ads.redirected\_to”](#app_adsredirected_to)
Type: `string`
URL to which the ads.txt resource was redirected.
#### `app_ads.account_count`
[Section titled “app\_ads.account\_count”](#app_adsaccount_count)
Type: `integer`
Number of advertising accounts listed in the ads.txt file.
#### `app_ads.account_types`
[Section titled “app\_ads.account\_types”](#app_adsaccount_types)
Type: `object`
Types of accounts (direct or reseller) listed in the ads.txt file.
##### `app_ads.account_types.direct`
[Section titled “app\_ads.account\_types.direct”](#app_adsaccount_typesdirect)
Type: `object`
Information about direct advertising accounts.
###### `app_ads.account_types.direct.domains`
[Section titled “app\_ads.account\_types.direct.domains”](#app_adsaccount_typesdirectdomains)
Type: `array`
List of domains with advertising accounts of this type.
###### `app_ads.account_types.direct.account_count`
[Section titled “app\_ads.account\_types.direct.account\_count”](#app_adsaccount_typesdirectaccount_count)
Type: `integer`
Number of advertising accounts of this type.
###### `app_ads.account_types.direct.domain_count`
[Section titled “app\_ads.account\_types.direct.domain\_count”](#app_adsaccount_typesdirectdomain_count)
Type: `integer`
Number of unique domains with advertising accounts of this type.
##### `app_ads.account_types.reseller`
[Section titled “app\_ads.account\_types.reseller”](#app_adsaccount_typesreseller)
Type: `object`
Information about reseller advertising accounts.
###### `app_ads.account_types.reseller.domains`
[Section titled “app\_ads.account\_types.reseller.domains”](#app_adsaccount_typesresellerdomains)
Type: `array`
List of domains with advertising accounts of this type.
###### `app_ads.account_types.reseller.account_count`
[Section titled “app\_ads.account\_types.reseller.account\_count”](#app_adsaccount_typesreselleraccount_count)
Type: `integer`
Number of advertising accounts of this type.
###### `app_ads.account_types.reseller.domain_count`
[Section titled “app\_ads.account\_types.reseller.domain\_count”](#app_adsaccount_typesresellerdomain_count)
Type: `integer`
Number of unique domains with advertising accounts of this type.
#### `app_ads.line_count`
[Section titled “app\_ads.line\_count”](#app_adsline_count)
Type: `integer`
Total number of lines in the ads.txt file.
#### `app_ads.variables`
[Section titled “app\_ads.variables”](#app_adsvariables)
Type: `array`
List of variables found in the ads.txt file.
#### `app_ads.variable_count`
[Section titled “app\_ads.variable\_count”](#app_adsvariable_count)
Type: `integer`
Number of variables found in the ads.txt file.
#### `app_ads.error`
[Section titled “app\_ads.error”](#app_adserror)
Type: `string`
Error message if fetch or parse failed.
### `sellers`
[Section titled “sellers”](#sellers)
Type: `object`
Contains information about the sellers.json file. See [IAB Sellers.json Specification](https://github.com/InteractiveAdvertisingBureau/Supply-Chain-Validation/blob/main/sellers-json.md).
#### `sellers.present`
[Section titled “sellers.present”](#sellerspresent)
Type: `boolean`
Indicates if the sellers.json file is present.
#### `sellers.status`
[Section titled “sellers.status”](#sellersstatus)
Type: `integer`
HTTP status code of the sellers.json file response.
#### `sellers.redirected`
[Section titled “sellers.redirected”](#sellersredirected)
Type: `boolean`
Indicates if the sellers.json file request was redirected.
#### `sellers.redirected_to`
[Section titled “sellers.redirected\_to”](#sellersredirected_to)
Type: `string`
URL to which the sellers.json resource was redirected.
#### `sellers.seller_count`
[Section titled “sellers.seller\_count”](#sellersseller_count)
Type: `integer`
Number of sellers listed in the sellers.json file.
#### `sellers.seller_types`
[Section titled “sellers.seller\_types”](#sellersseller_types)
Type: `object`
Types of sellers (publisher, intermediary, both) listed in the sellers.json file.
##### `sellers.seller_types.publisher`
[Section titled “sellers.seller\_types.publisher”](#sellersseller_typespublisher)
Type: `object`
Information about publisher sellers.
###### `sellers.seller_types.publisher.domains`
[Section titled “sellers.seller\_types.publisher.domains”](#sellersseller_typespublisherdomains)
Type: `array`
List of domains associated with this seller type.
###### `sellers.seller_types.publisher.seller_count`
[Section titled “sellers.seller\_types.publisher.seller\_count”](#sellersseller_typespublisherseller_count)
Type: `integer`
Number of sellers of this type.
###### `sellers.seller_types.publisher.domain_count`
[Section titled “sellers.seller\_types.publisher.domain\_count”](#sellersseller_typespublisherdomain_count)
Type: `integer`
Number of unique domains associated with this seller type.
##### `sellers.seller_types.intermediary`
[Section titled “sellers.seller\_types.intermediary”](#sellersseller_typesintermediary)
Type: `object`
Information about intermediary sellers.
###### `sellers.seller_types.intermediary.domains`
[Section titled “sellers.seller\_types.intermediary.domains”](#sellersseller_typesintermediarydomains)
Type: `array`
List of domains associated with this seller type.
###### `sellers.seller_types.intermediary.seller_count`
[Section titled “sellers.seller\_types.intermediary.seller\_count”](#sellersseller_typesintermediaryseller_count)
Type: `integer`
Number of sellers of this type.
###### `sellers.seller_types.intermediary.domain_count`
[Section titled “sellers.seller\_types.intermediary.domain\_count”](#sellersseller_typesintermediarydomain_count)
Type: `integer`
Number of unique domains associated with this seller type.
##### `sellers.seller_types.both`
[Section titled “sellers.seller\_types.both”](#sellersseller_typesboth)
Type: `object`
Information about sellers who are both publishers and intermediaries.
###### `sellers.seller_types.both.domains`
[Section titled “sellers.seller\_types.both.domains”](#sellersseller_typesbothdomains)
Type: `array`
List of domains associated with this seller type.
###### `sellers.seller_types.both.seller_count`
[Section titled “sellers.seller\_types.both.seller\_count”](#sellersseller_typesbothseller_count)
Type: `integer`
Number of sellers of this type.
###### `sellers.seller_types.both.domain_count`
[Section titled “sellers.seller\_types.both.domain\_count”](#sellersseller_typesbothdomain_count)
Type: `integer`
Number of unique domains associated with this seller type.
#### `sellers.passthrough_count`
[Section titled “sellers.passthrough\_count”](#sellerspassthrough_count)
Type: `integer`
Number of passthrough sellers listed in the sellers.json file.
#### `sellers.confidential_count`
[Section titled “sellers.confidential\_count”](#sellersconfidential_count)
Type: `integer`
Number of confidential sellers listed in the sellers.json file.
#### `sellers.error`
[Section titled “sellers.error”](#sellerserror)
Type: `string`
Error message if fetch or parse failed.
# Privacy custom metric
> Reference docs for the privacy custom metric
*Appears in: [`custom_metrics`](/reference/structs/custom-metrics/) struct*\
*As: [`privacy`](/reference/structs/custom-metrics/#privacy)*
## Schema
[Section titled “Schema”](#schema)
### `iab_tcf_v1`
[Section titled “iab\_tcf\_v1”](#iab_tcf_v1)
Type: `object`
IAB Transparency and Consent Framework v1 settings and vendor consents. See [IAB TCF v1.1](https://github.com/InteractiveAdvertisingBureau/GDPR-Transparency-and-Consent-Framework/blob/master/CMP%20JS%20API%20v1.1%20Final.md).
#### `iab_tcf_v1.present`
[Section titled “iab\_tcf\_v1.present”](#iab_tcf_v1present)
Type: `boolean`
Whether the [`__cmp` API function](https://github.com/InteractiveAdvertisingBureau/GDPR-Transparency-and-Consent-Framework/blob/master/CMP%20JS%20API%20v1.1%20Final.md#what-api-will-need-to-be-provided-by-the-cmp-) is present on the window object.
#### `iab_tcf_v1.data`
[Section titled “iab\_tcf\_v1.data”](#iab_tcf_v1data)
Type: `object`
TCF v1 vendor consents data returned by `getVendorConsents`. See [VendorConsents](https://github.com/InteractiveAdvertisingBureau/GDPR-Transparency-and-Consent-Framework/blob/master/CMP%20JS%20API%20v1.1%20Final.md#vendorconsents-).
#### `iab_tcf_v1.compliant_setup`
[Section titled “iab\_tcf\_v1.compliant\_setup”](#iab_tcf_v1compliant_setup)
Type: `boolean`
Verifies whether the TCF v1 CMP setup is compliant with IAB standards.
### `iab_tcf_v2`
[Section titled “iab\_tcf\_v2”](#iab_tcf_v2)
Type: `object`
IAB Transparency and Consent Framework v2 settings and vendor consents. See [IAB TCF v2](https://github.com/InteractiveAdvertisingBureau/GDPR-Transparency-and-Consent-Framework/blob/master/TCFv2/IAB%20Tech%20Lab%20-%20CMP%20API%20v2.md).
#### `iab_tcf_v2.present`
[Section titled “iab\_tcf\_v2.present”](#iab_tcf_v2present)
Type: `boolean`
Whether the [`__tcfapi` API function](https://github.com/InteractiveAdvertisingBureau/GDPR-Transparency-and-Consent-Framework/blob/master/TCFv2/IAB%20Tech%20Lab%20-%20CMP%20API%20v2.md#how-does-the-cmp-provide-the-api) is present on the window object.
#### `iab_tcf_v2.data`
[Section titled “iab\_tcf\_v2.data”](#iab_tcf_v2data)
Type: `object`
TCF v2 vendor consents data returned by `getTCData`. See [TCData](https://github.com/InteractiveAdvertisingBureau/GDPR-Transparency-and-Consent-Framework/blob/master/TCFv2/IAB%20Tech%20Lab%20-%20CMP%20API%20v2.md#tcdata).
#### `iab_tcf_v2.compliant_setup`
[Section titled “iab\_tcf\_v2.compliant\_setup”](#iab_tcf_v2compliant_setup)
Type: `boolean`
Verifies whether the TCF v2 CMP setup is compliant with IAB standards.
### `iab_gpp`
[Section titled “iab\_gpp”](#iab_gpp)
Type: `object`
Global Privacy Platform (GPP) ping response data. See [Global-Privacy-Platform](https://github.com/InteractiveAdvertisingBureau/Global-Privacy-Platform).
#### `iab_gpp.present`
[Section titled “iab\_gpp.present”](#iab_gpppresent)
Type: `boolean`
Whether the `__gpp` API function is present on the window object.
#### `iab_gpp.data`
[Section titled “iab\_gpp.data”](#iab_gppdata)
Type: `object`
Ping response data returned by the `__gpp` API.
### `iab_usp`
[Section titled “iab\_usp”](#iab_usp)
Type: `object`
IAB US Privacy User Signal Mechanism (USP API) data. See [USPrivacy](https://github.com/InteractiveAdvertisingBureau/USPrivacy).
#### `iab_usp.present`
[Section titled “iab\_usp.present”](#iab_usppresent)
Type: `boolean`
Whether the `__uspapi` API function is present on the window object.
#### `iab_usp.privacy_string`
[Section titled “iab\_usp.privacy\_string”](#iab_uspprivacy_string)
Type: `string`
US Privacy string returned by `getUSPData`.
### `navigator_doNotTrack`
[Section titled “navigator\_doNotTrack”](#navigator_donottrack)
Type: `boolean`
Whether the browser’s “Do Not Track” setting was accessed or detected in response bodies. See [EFF Do Not Track](https://www.eff.org/issues/do-not-track).
### `navigator_globalPrivacyControl`
[Section titled “navigator\_globalPrivacyControl”](#navigator_globalprivacycontrol)
Type: `boolean`
Whether the Global Privacy Control (GPC) property was accessed or detected in response bodies. See [Global Privacy Control](https://globalprivacycontrol.org/).
### `document_permissionsPolicy`
[Section titled “document\_permissionsPolicy”](#document_permissionspolicy)
Type: `boolean`
Whether document Permissions Policy is referenced in response bodies. See [W3C Permissions Policy](https://www.w3.org/TR/permissions-policy-1/#introspection). Iframes properties in `almanac` and `security` custom metrics.
### `document_featurePolicy`
[Section titled “document\_featurePolicy”](#document_featurepolicy)
Type: `boolean`
Whether document Feature Policy (legacy Permissions Policy) is referenced in response bodies.
### `referrerPolicy`
[Section titled “referrerPolicy”](#referrerpolicy)
Type: `object`
Referrer policy declared for the entire document, subresource requests, or link relations. See [MDN Referrer-Policy](https://developer.mozilla.org/en-US/docs/Web/HTTP/Headers/Referrer-Policy).
#### `referrerPolicy.entire_document_policy`
[Section titled “referrerPolicy.entire\_document\_policy”](#referrerpolicyentire_document_policy)
Type: `string`
Referrer policy set for the entire document using meta tag.
#### `referrerPolicy.individual_requests`
[Section titled “referrerPolicy.individual\_requests”](#referrerpolicyindividual_requests)
Type: `array